
Apertus 1.5 notes detail open models that understand images and audio
Technical notes published on October 15 say Apertus 1.5 adds multimodal input, an optional thinking mode, a 262,144-token context window, and improved tool use to its 8B and 70B models.
AT A GLANCE
Key points
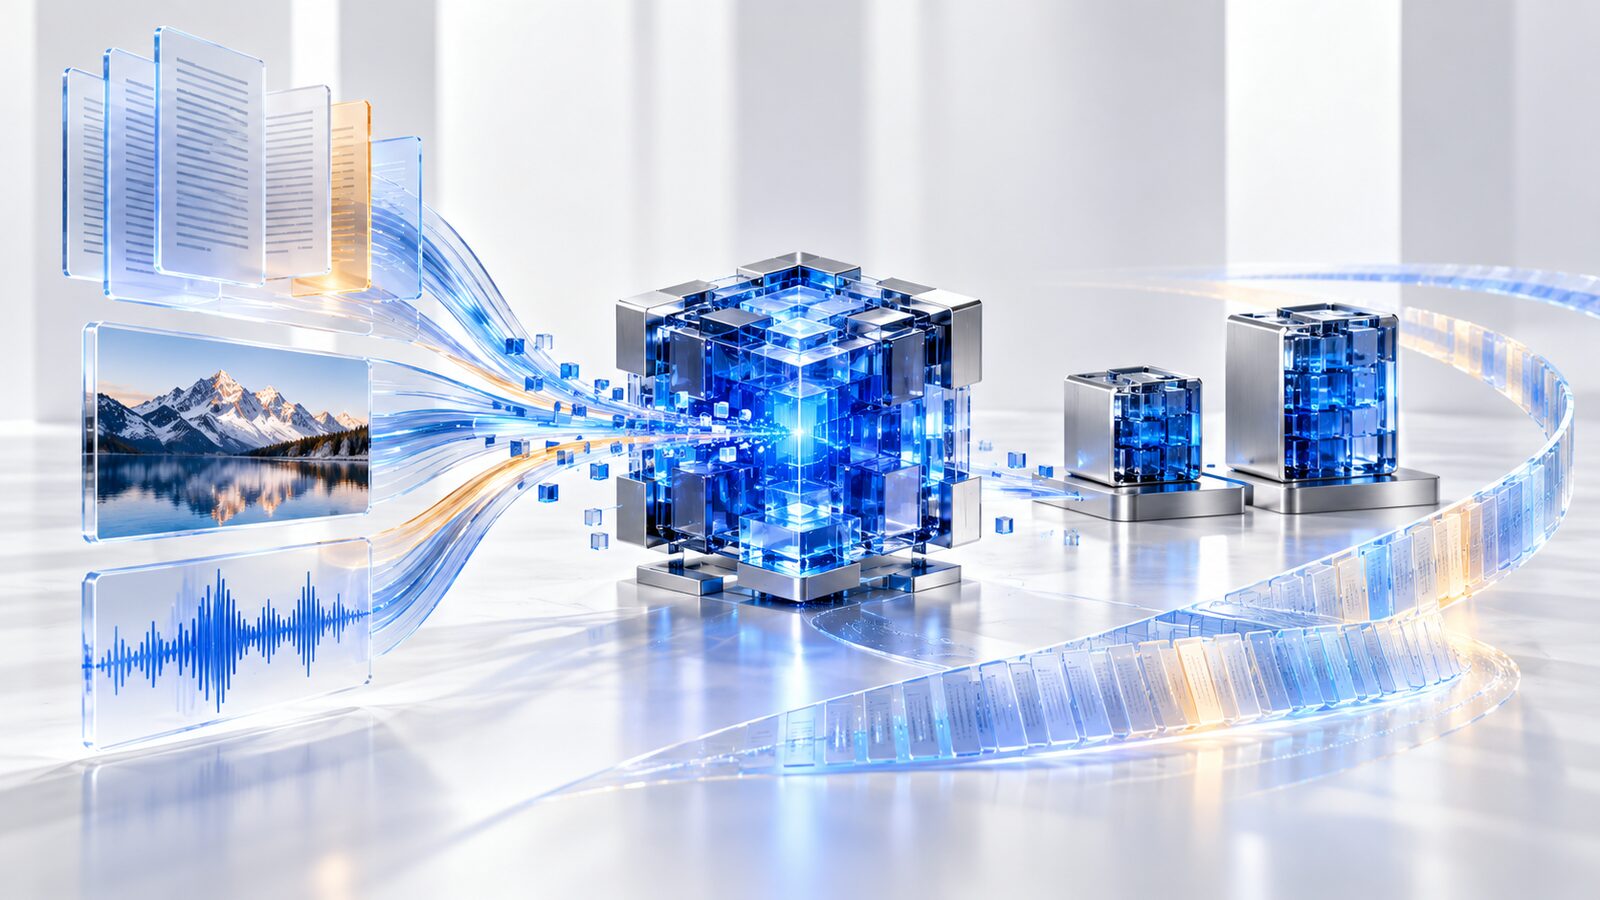
- The 8B and 70B models process images and audio in the same token sequence as text.
- The context window grows fourfold to 262,144 tokens.
- Weights are released under Apache 2.0 alongside data, recipes, and intermediate checkpoints.
- The models understand multimodal inputs but generate text only.
What is changing?
Swiss AI published the technical notes for Apertus 1.5 on October 15. The 8B and 70B weights, released in July under Apache 2.0, now process images and audio alongside text in a single token sequence. Speech understanding remains experimental, and the models generate text only.
The release expands the context window fourfold over Apertus 1.0 to 262,144 tokens and adds an optional thinking mode, stronger instruction following, and improved tool use. Continued pretraining adds 4 trillion new text and multimodal tokens to the 8B model and 2 trillion to the 70B model.
Alongside the weights, the project publishes data sources, training recipes, intermediate checkpoints, and machine-readable evaluation cards. Provider benchmarks show gains, while noting the release still trails frontier open-weight models; production teams should repeat domain-specific quality and latency tests.
Explore the original sources
Source date: 15 October 2026.
Published by AI Radar: 16 Oct 2026, 22:10 (Istanbul, UTC+3).
FOLLOW THE TOPIC
Topics and tags
Share your discovery.
Send this story to a friend.
Reader comments
What do you think about this development? Share your experience or question. Comments are published after editorial approval.
Your name/nickname and comment become public if approved. Read: Privacy notice.



Loading comments…