
Box Content Retrieval prepares Nemotron-powered context for agents
Box introduced a Content Retrieval layer that delivers smaller, relevant slices of enterprise content to AI agents while preserving access permissions.
AT A GLANCE
Key points
- Nemotron Embed powers retrieval across multiple Box content types.
- Box reports up to 4× faster retrieval and 90% lower token use.
- The rollout is planned for Enterprise Advanced customers in early 2027.
What is changing?
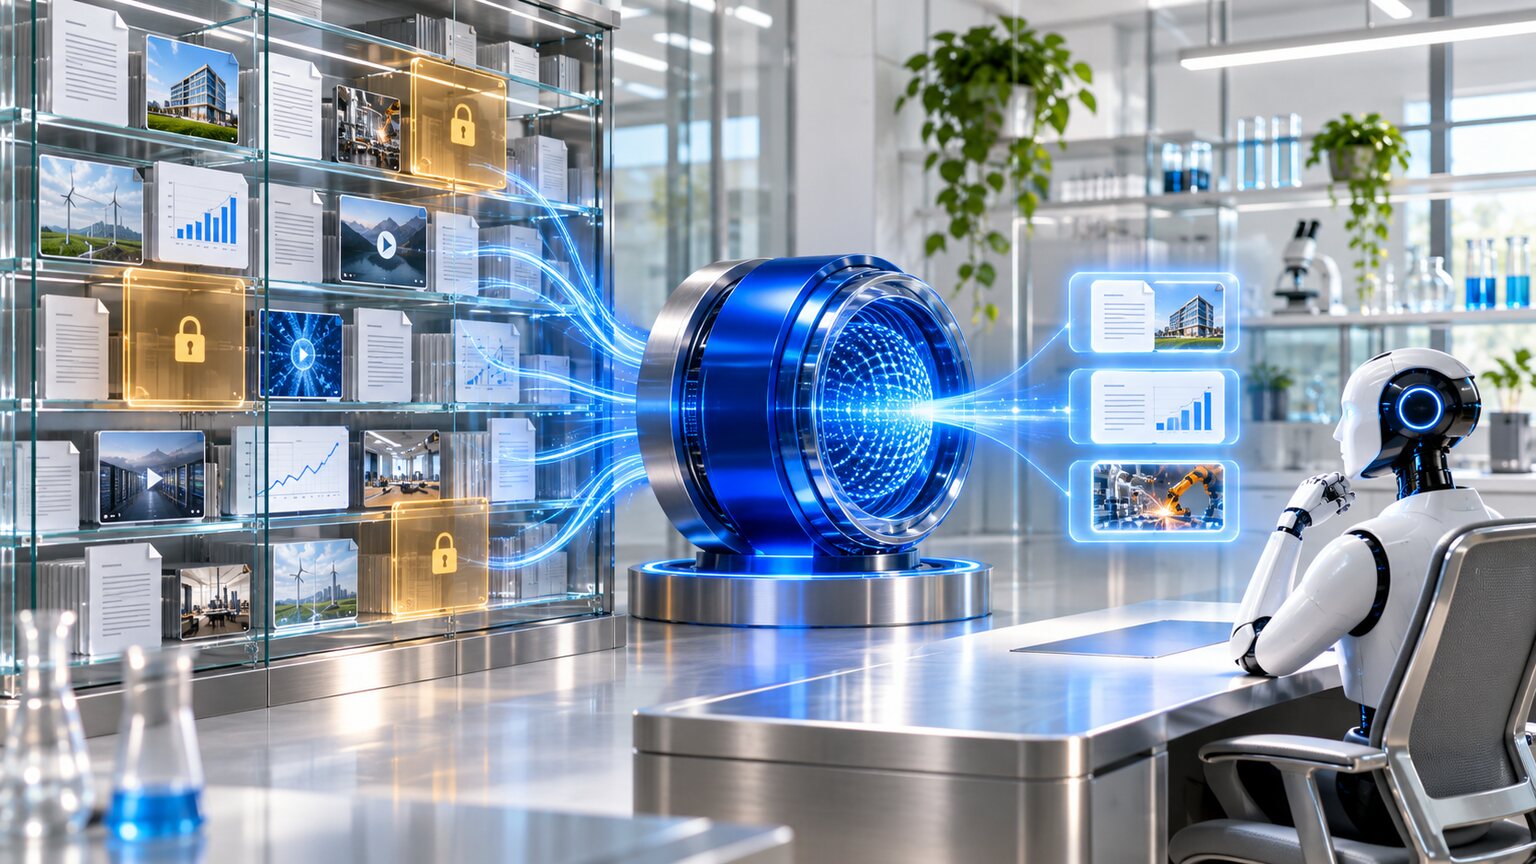
Box introduced Content Retrieval, a layer designed for AI agents, at its developer conference. According to TechCrunch, the system combines NVIDIA’s Nemotron Embed model with Box content, metadata and access permissions to extract relevant segments from documents, images, charts and videos. The goal is to give an agent only the context needed for a task instead of sending an entire file to a model.
Box and NVIDIA claim tests showed up to four times faster retrieval, 20 percent fewer errors and as much as 90 percent lower token use than the existing approach. These are provider-reported measurements, not an independent benchmark. Box says Content Retrieval will begin rolling out to Enterprise Advanced customers in early 2027.
For production teams, the change could reduce context cost and accidental exposure when agents work with enterprise knowledge. The practical benefit will depend on independent testing across file types and each organization’s permission structure.
Explore the original sources
Source date: 5 November 2026.
Published by AI Radar: 5 Nov 2026, 19:04 (Istanbul, UTC+3). Updated: 5 Nov 2026, 19:13.
FOLLOW THE TOPIC
Topics and tags
Share your discovery.
Send this story to a friend.
Reader comments
What do you think about this development? Share your experience or question. Comments are published after editorial approval.
Your name/nickname and comment become public if approved. Read: Privacy notice.





Loading comments…