
Dharma Field Extractor turns documents into JSON that follows a requested schema
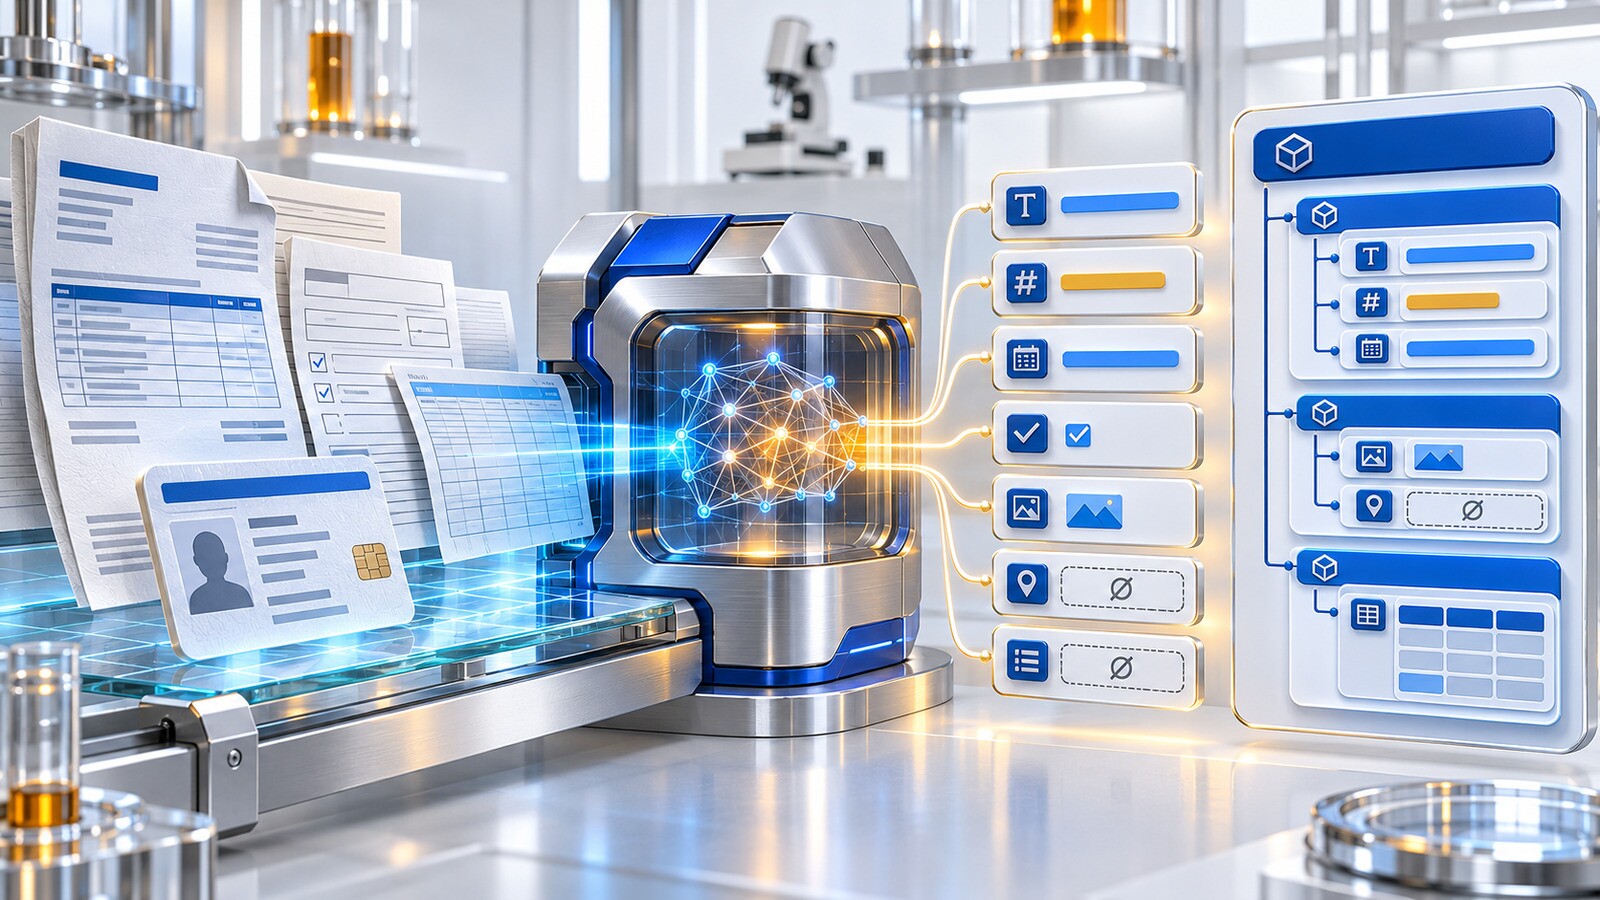
Dharma AI’s 2-billion-parameter Field Extractor model extracts open or schema-directed fields from document images as typed, nested JSON.
AT A GLANCE
Key points
- The model supports open extraction or exact schema guidance and returns typed, nested JSON.
- The 2-billion-parameter checkpoint was trained with LoRA on 43,384 examples.
- The reported 0.834 score and 6–147× cost claim come from the provider’s own benchmark.
What is changing?
Dharma AI released a 2-billion-parameter Field Extractor model for structured extraction from document images. Users can define field names, types, and nested structures alongside a document; when a value is missing, the model returns null instead of inventing one. The same checkpoint is designed to work across document types without task-specific retraining.
The model builds on DharmaOCR-LITE v1.1 and was trained with LoRA on 43,384 examples. The training mix spans multiple industries, languages, tables, and key-value layouts.
Dharma’s own evaluation used 546 documents across three scenarios, totaling 1,638 cases. The company reports a score of 0.834, compared with 0.816 for Claude Opus 5 and 0.741 for GPT‑5.6 Luna. Its 6–147× cost claim is based on a single L40S at $2.24 per hour and list pricing; it is not a sales price.
Explore the original sources
Source date: 4 November 2026.
Published by AI Radar: 5 Nov 2026, 03:08 (Istanbul, UTC+3).
FOLLOW THE TOPIC
Topics and tags
Share your discovery.
Send this story to a friend.
Reader comments
What do you think about this development? Share your experience or question. Comments are published after editorial approval.
Your name/nickname and comment become public if approved. Read: Privacy notice.






Loading comments…