
Hugging Face tests a 4× reduction with pooling-aware training
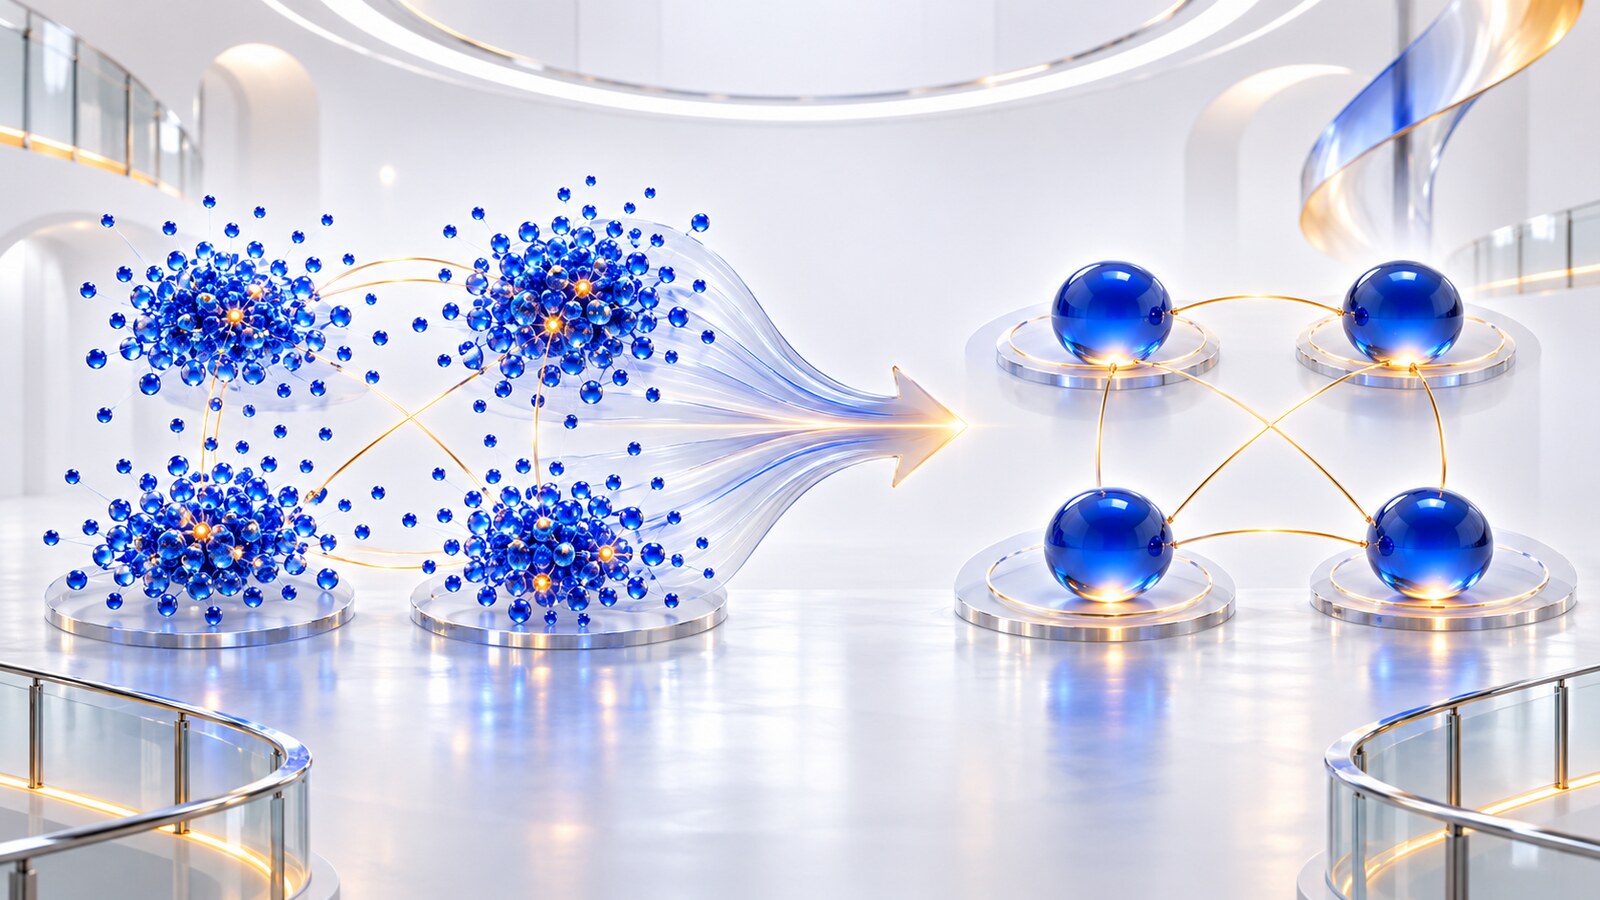
Pooling-aware training reduced document vectors to one quarter in a multi-vector search index while retaining 97.8% of the unchanged nDCG@10 performance.
AT A GLANCE
Key points
- Four-times pooling cuts the number of stored document vectors to one quarter.
- Pooling-aware training retained 97.8% of unchanged nDCG@10 performance.
- The conventionally trained comparison retained 94.6% at the same setting.
What is changing?
Hugging Face has published a method that incorporates token pooling into the training of multi-vector embedding models. These architectures store a separate representation for each token instead of compressing a document into one vector, improving fine-grained matching while increasing index size and query cost. Token pooling reduces the number of stored vectors by clustering similar document vectors and replacing them with representative means.
In the NanoBEIR evaluation reported in the article, 4× pooling retained 94.6% of the unchanged nDCG@10 performance for a conventionally trained model. Pooling-aware training raised that figure to 97.8%. These are provider-run experiments and do not guarantee the same trade-off in every domain. The method offers a measurable optimization option for teams building smaller indexes for RAG, semantic search and visual document retrieval.
Explore the original sources
Source date: 11 November 2026.
Published by AI Radar: 11 Nov 2026, 19:12 (Istanbul, UTC+3). Updated: 11 Nov 2026, 19:13.
FOLLOW THE TOPIC
Topics and tags
Share your discovery.
Send this story to a friend.
Reader comments
What do you think about this development? Share your experience or question. Comments are published after editorial approval.
Your name/nickname and comment become public if approved. Read: Privacy notice.





Loading comments…