
Microsoft’s ThinkingBox trains agents on actual database outcomes
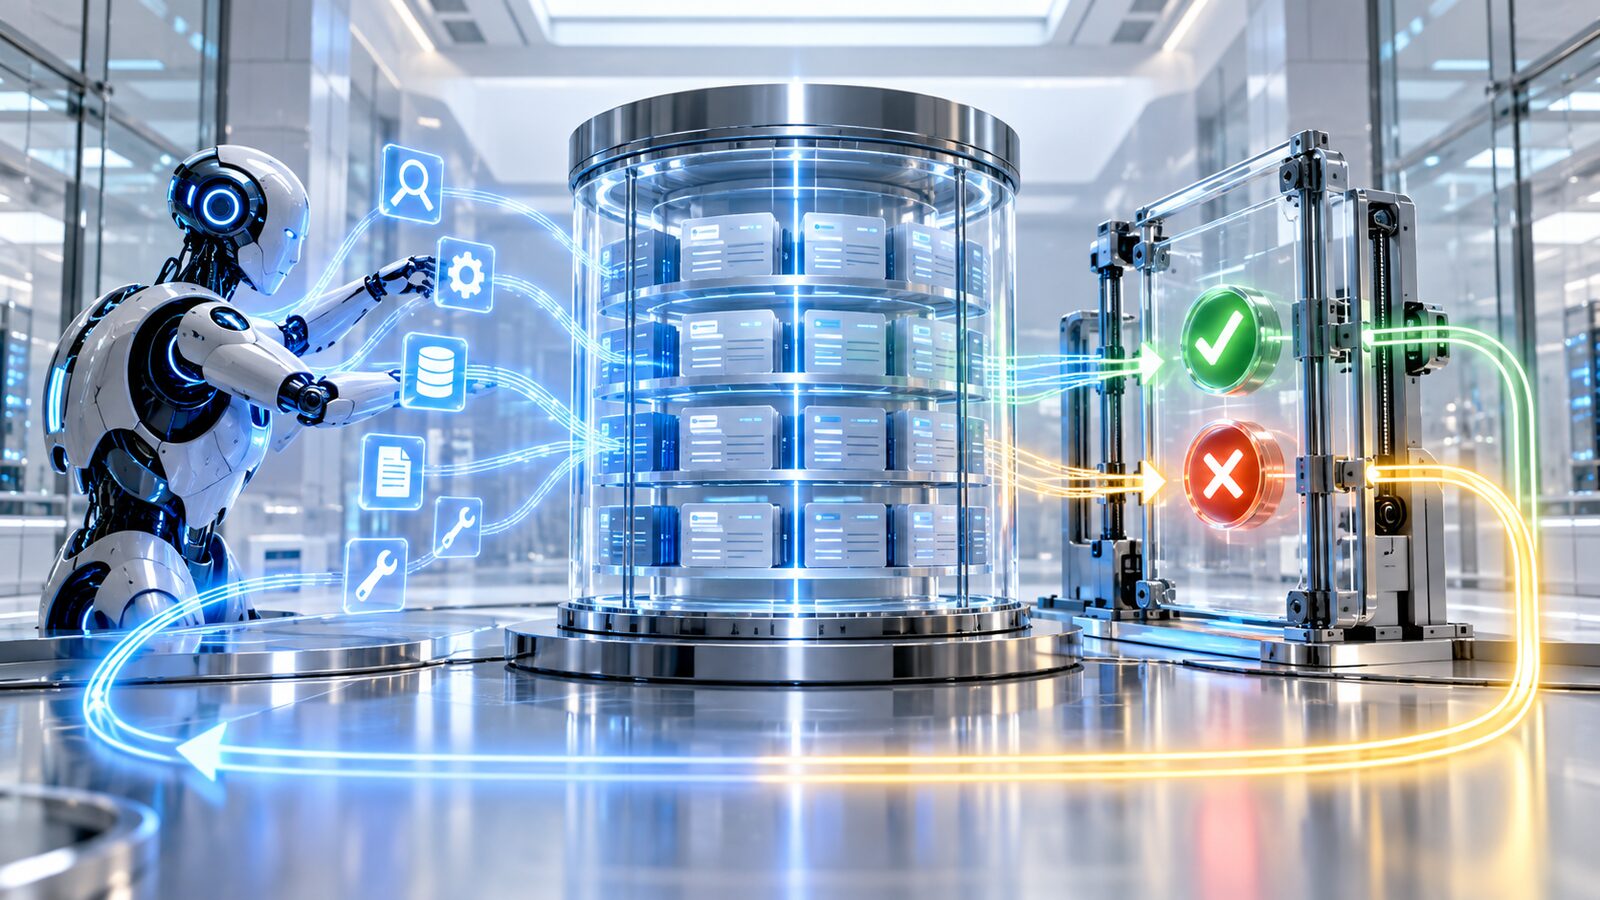
Microsoft and Hugging Face released the ThinkingBox training stack, which turns the final database state left by an agent into an executable reinforcement-learning reward.
AT A GLANCE
Key points
- ThinkingBox converts final database state into an executable reward.
- Qwen3.8-27B average success increased from 51.70% to 60.78%.
- Tasks completed correctly on all 20 attempts increased from 38 to 107.
- The training code was released under the MIT licence.
What is changing?
Microsoft and Hugging Face released ThinkingBox-Training on October 22. Instead of trusting an agent’s claim that a task is complete, the system evaluates the actual records left in the database with executable checks. That binary outcome becomes a reinforcement-learning reward on tasks outside ThinkingBox-Bench.
The team trained Qwen3.8-27B for 50 GRPO steps on 187 selected tasks. According to the providers’ evaluation across 507 tasks with 20 attempts each, average success rose from 51.70% to 60.78%, while the number of tasks completed correctly on all 20 attempts increased from 38 to 107.
The number of tasks solved at least once fell from 453 to 446, however. The result suggests the model became more repeatable rather than broader. The training code is available under the MIT licence; the validated setup uses 24 H100 GPUs, while the private 187-task training pool is not released.
Explore the original sources
Source date: 23 October 2026.
Published by AI Radar: 23 Oct 2026, 06:01 (Istanbul, UTC+3).
FOLLOW THE TOPIC
Topics and tags
Share your discovery.
Send this story to a friend.
Reader comments
What do you think about this development? Share your experience or question. Comments are published after editorial approval.
Your name/nickname and comment become public if approved. Read: Privacy notice.




Loading comments…