
Musubi PolicyLM evaluates content rules with a compact model
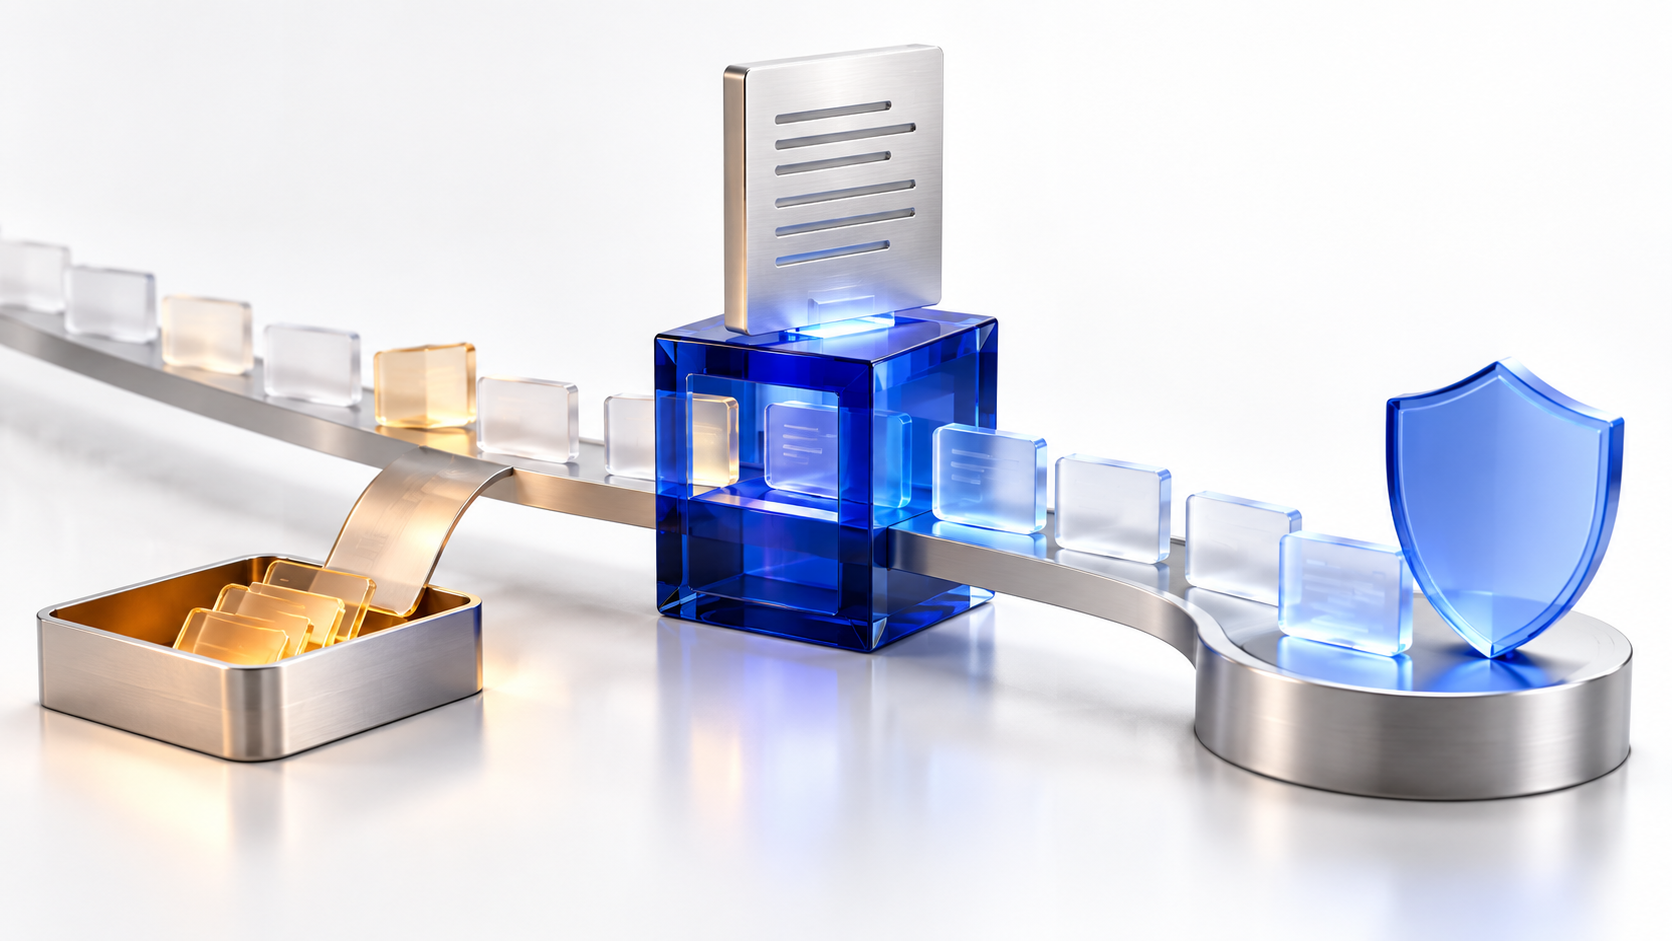
The 1.7-billion-parameter open-weight model scores text against supplied policy categories. It is not a chatbot generating free-form explanations.
What is changing?
Musubi Labs introduced PolicyLM-1.7B on October 6. Apache 2.0-licensed weights support classification against custom content rules. It returns scores from zero to one for each category, rather than free-form reasoning.
Each message is evaluated separately, without automatic conversation-history handling. Policy and message share a 2,048-token limit. Musubi reports a 35 ms median for six categories on a 24 GB NVIDIA L4, not a guarantee for every device. It tested 19 languages, with strongest results in English.
AI Radar perspective: A small locally runnable model could help comment and community moderation. Turkish accuracy and false-blocking rates need separate tests; the language count alone does not guarantee Turkish quality.
Explore the original sources
Source date: 6 October 2026.
Published by AI Radar: 7 Oct 2026, 19:05 (Istanbul, UTC+3).
FOLLOW THE TOPIC
Topics and tags
Share your discovery.
Send this story to a friend.
Reader comments
What do you think about this development? Share your experience or question. Comments are published after editorial approval.
Your name/nickname and comment become public if approved. Read: Privacy notice.





Loading comments…