
Together Compiler continuously retunes production inference for changing models
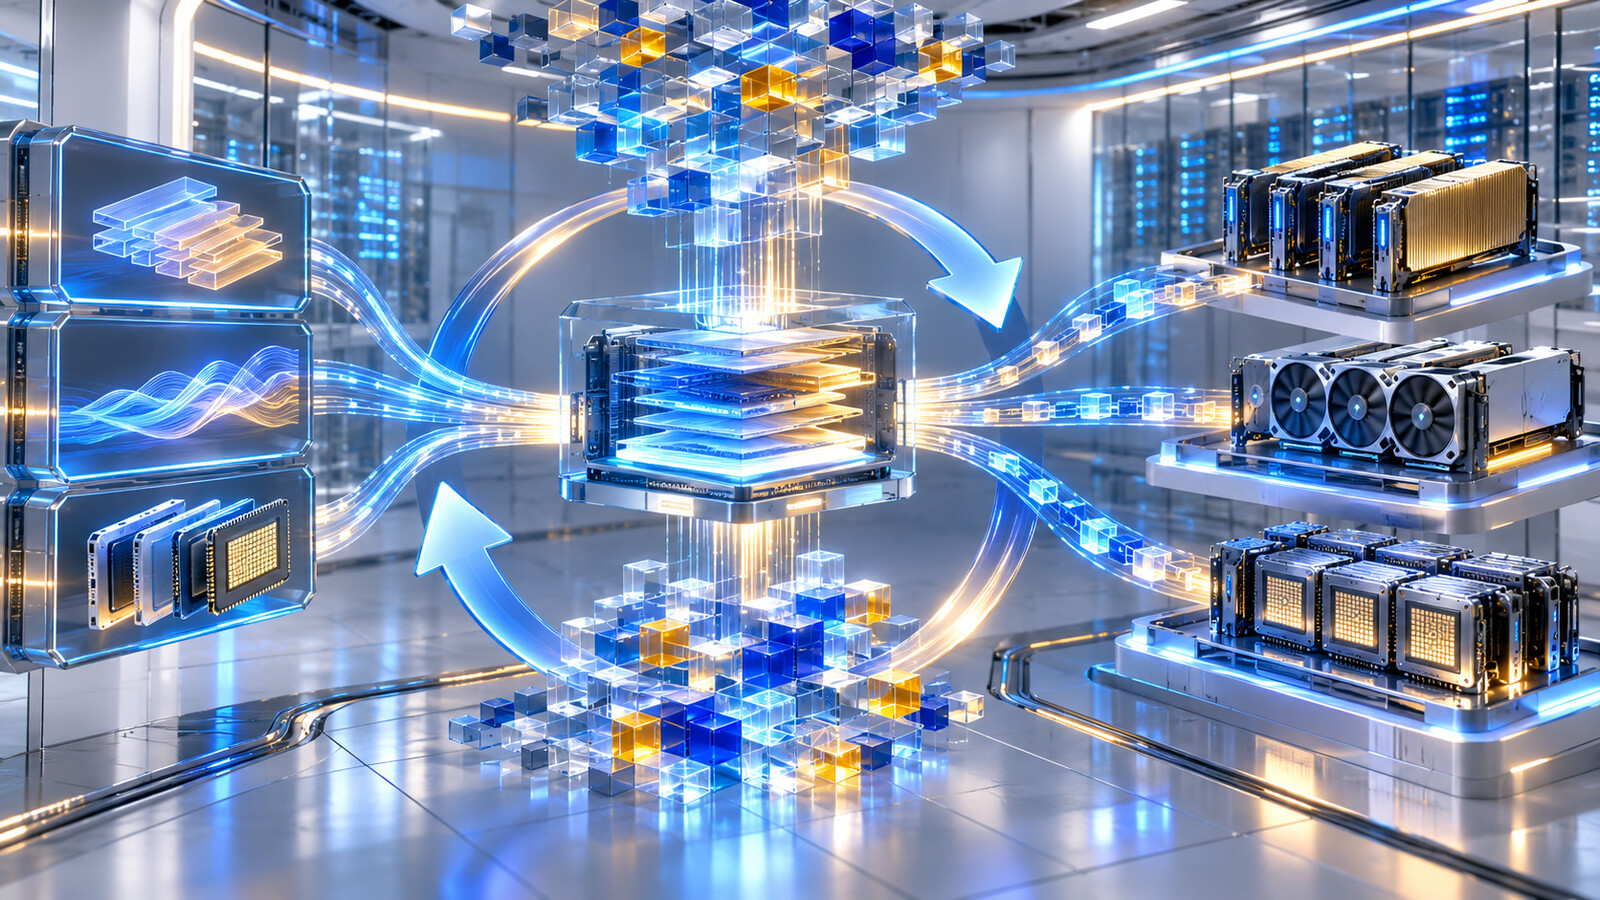
Together AI announced Polymorphic Inference, where agents continuously optimize inference code for models, traffic and GPU hardware.
AT A GLANCE
Key points
- Agents retune inference code for the model, traffic and GPU hardware.
- Together Compiler is the first implementation and is moving into production workloads.
- Reported speedups are provider measurements, not an independent benchmark.
What is changing?
Together AI announced its Polymorphic Inference initiative and its first implementation, Together Compiler, on November 4. The system is designed to use agents to automatically retune inference code for new model architectures, real traffic patterns and NVIDIA and AMD hardware. The company says Compiler is already running across some production workloads.
In early results shared by Together, Compiler delivered up to a 1.3x speedup over hand-written megakernels for Llama 1B in specific tests, a 1.5x speedup on a MiniMax M3 layer and a 1.7–2.5x speedup on Kimi K3’s long-request step. These are provider measurements, not an independent benchmark.
The approach aims to shorten the weeks of kernel optimization often needed to put new open models into production. Production teams should separately validate quality parity, latency distribution, energy use and durability across traffic mixes.
Explore the original sources
Source date: 4 November 2026.
Published by AI Radar: 4 Nov 2026, 18:14 (Istanbul, UTC+3).
FOLLOW THE TOPIC
Topics and tags
Share your discovery.
Send this story to a friend.
Reader comments
What do you think about this development? Share your experience or question. Comments are published after editorial approval.
Your name/nickname and comment become public if approved. Read: Privacy notice.




Loading comments…