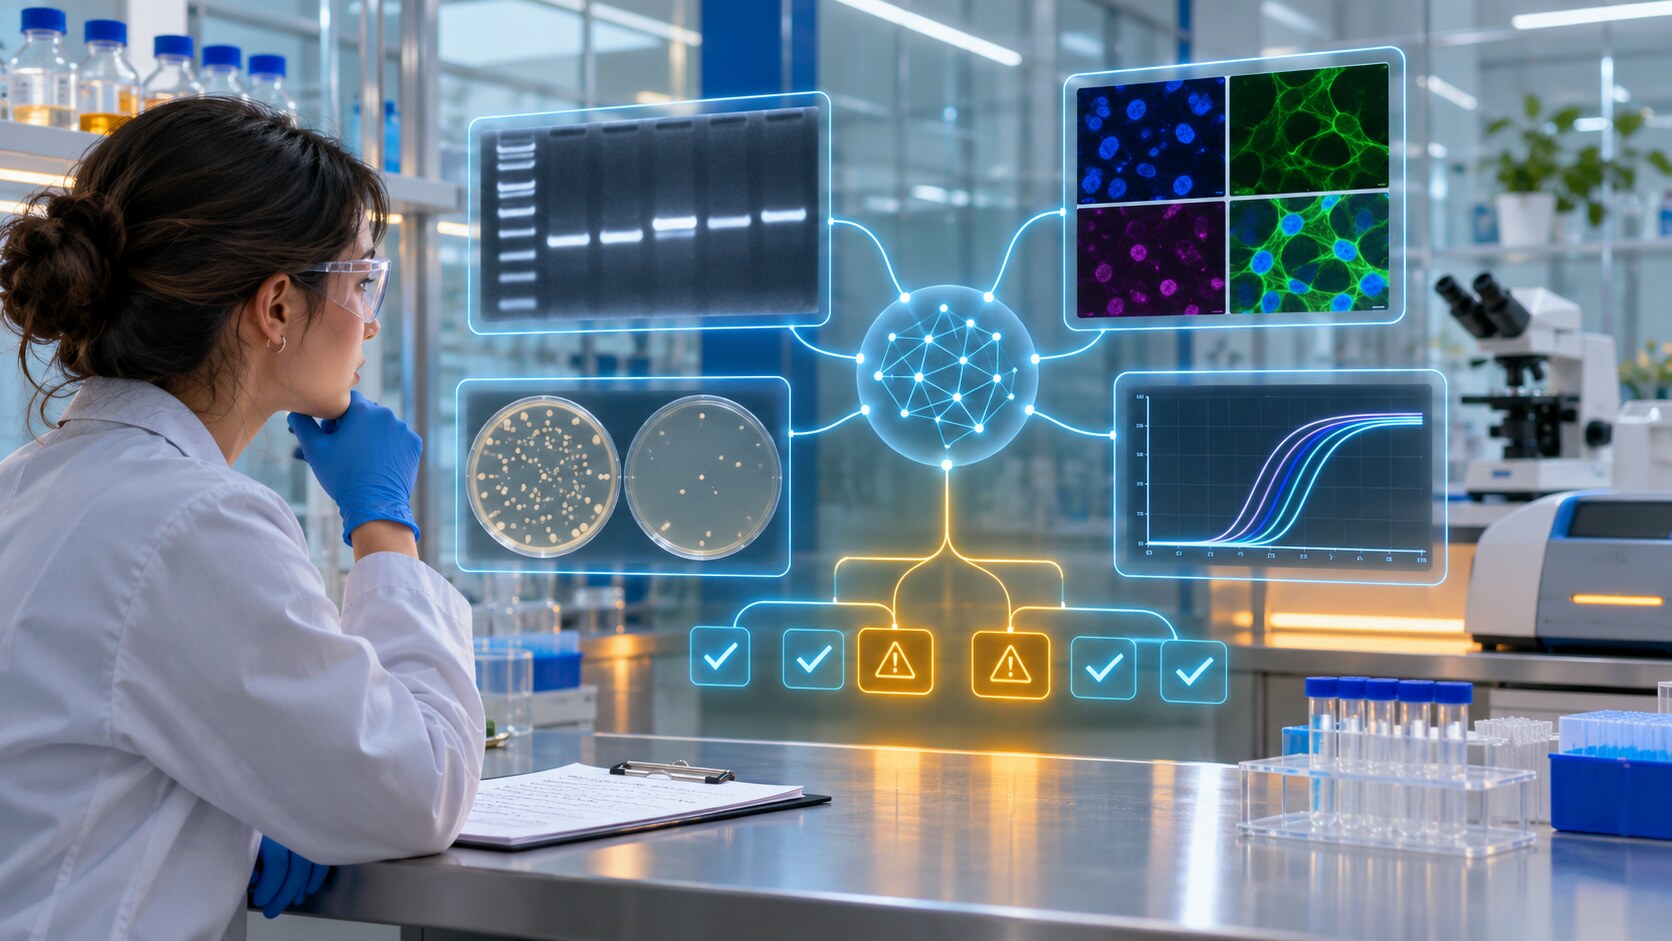
OpenAI’s BioBasicsBench evaluates AI agents across 100 routine wet-lab tasks
BioBasicsBench, developed by OpenAI and Ligo, measures whether AI agents can interpret raw experimental data, catch errors, and recognize the limits of evidence across 100 routine wet-lab tasks.
2 min readRead story