
Hugging Face adds Egyptian and Nigerian English to the Open ASR Leaderboard
The Open ASR Leaderboard added two private conversational datasets for Egyptian and Nigerian English to evaluate speech-recognition models across a broader range of accents.
AT A GLANCE
Key points
- The update adds 1.34 hours of Egyptian English and 1.55 hours of Nigerian English private speech data.
- Both sets contain natural conversational speech with disfluencies preserved.
- The leaderboard now reports US and non-US accents and World Englishes groups separately.
What is changing?
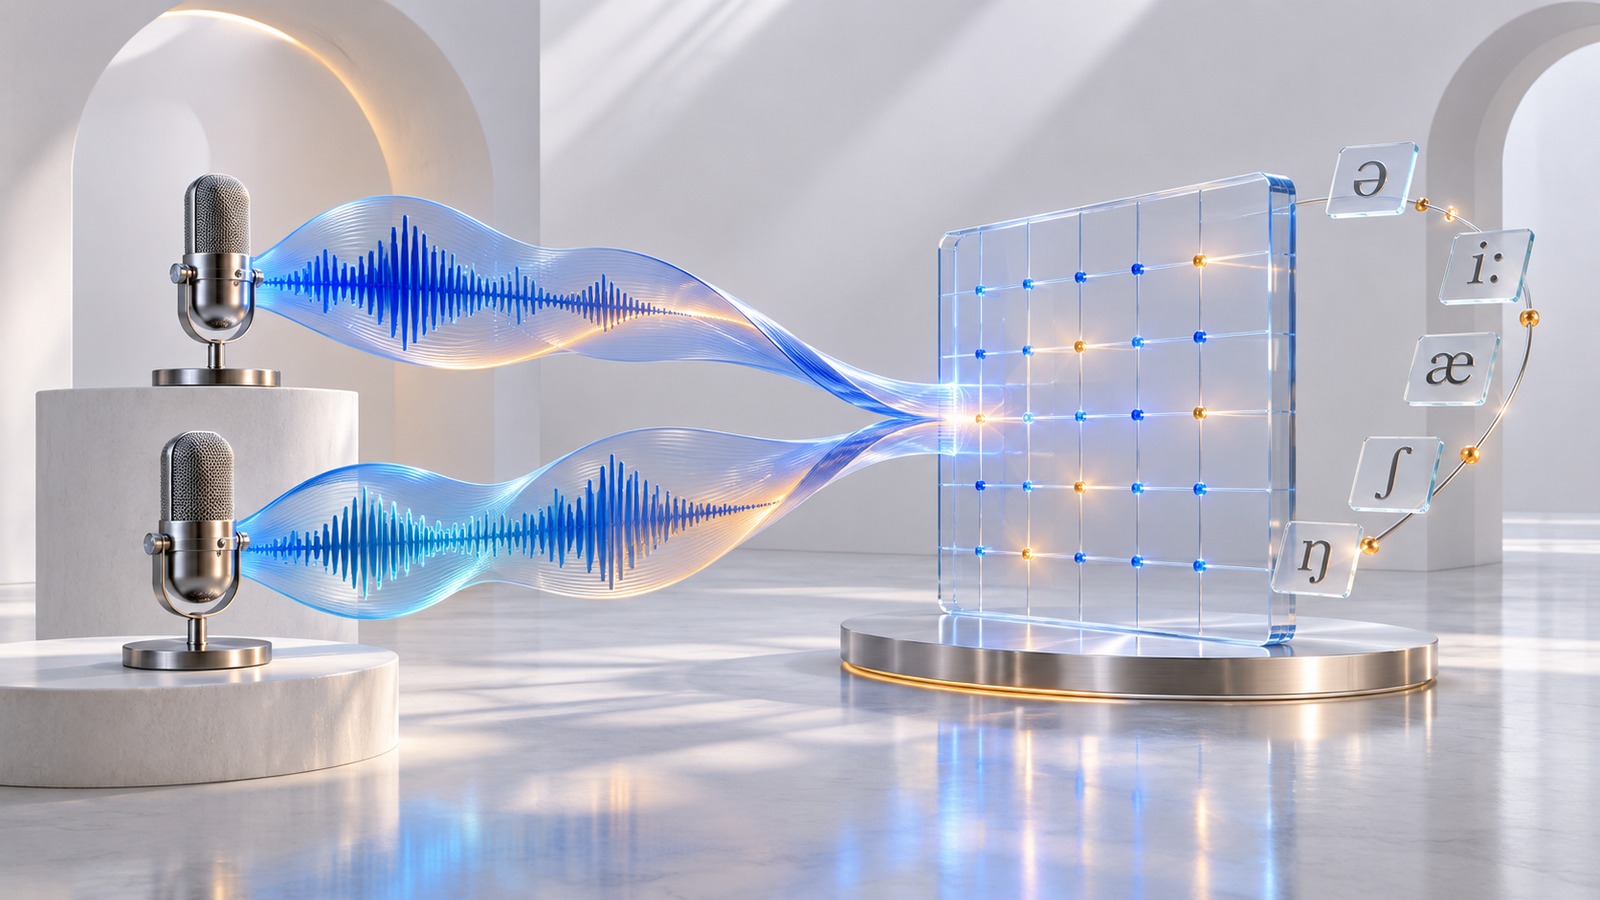
Hugging Face and Liva AI added Egyptian and Nigerian English to the private evaluation section of the Open ASR Leaderboard. The new sets contain 1.34 hours of Egyptian English and 1.55 hours of Nigerian English. Both feature natural, conversational speech, with punctuation, casing, and disfluencies preserved in the transcripts.
The leaderboard can now separately report US versus non-US accents and Inner Circle versus Outer and Expanding Circle groups under Kachru’s World Englishes framework. Keeping the data private is intended to reduce the risk of models being overfitted to known test examples. The update does not introduce a new speech model; it makes consistency across different English accents more visible for existing ASR systems.
Explore the original sources
Source date: 6 November 2026.
Published by AI Radar: 6 Nov 2026, 14:02 (Istanbul, UTC+3).
FOLLOW THE TOPIC
Topics and tags
Share your discovery.
Send this story to a friend.
Reader comments
What do you think about this development? Share your experience or question. Comments are published after editorial approval.
Your name/nickname and comment become public if approved. Read: Privacy notice.




Loading comments…