
Adobe Research presents Project Doki for text-native video authoring
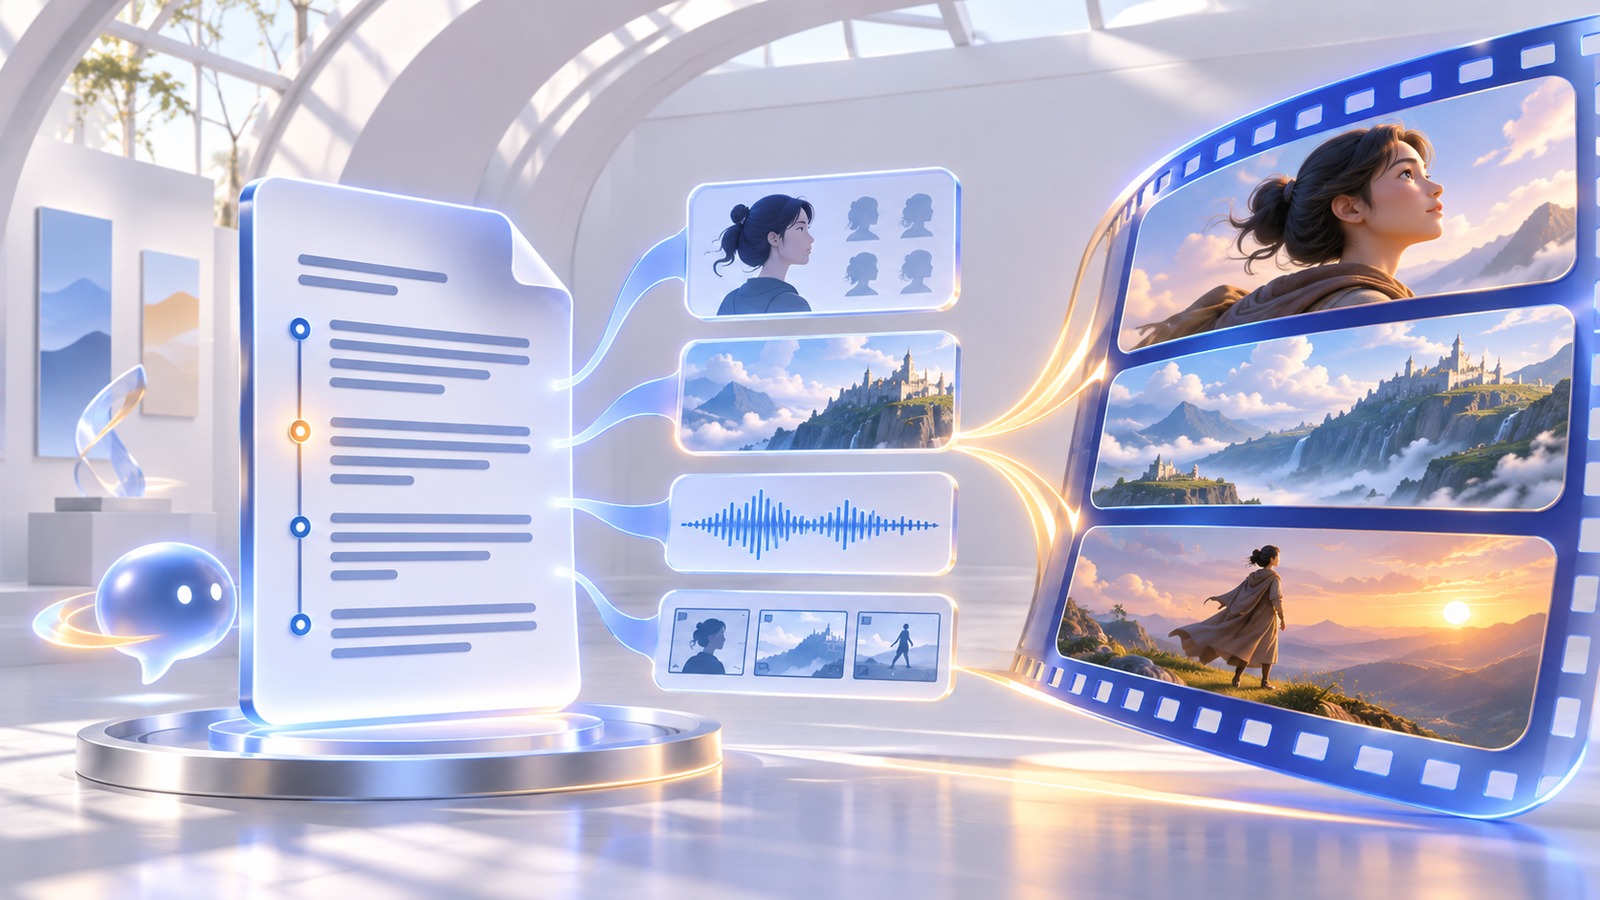
The UIST 2026-honored Project Doki research introduces an experimental video-authoring approach that manages characters, scenes, shots, edits, and audio through a single text document.
AT A GLANCE
Key points
- Project Doki combines characters, scenes, shots, edits, and audio in one text document.
- Inline previews and a conversational AI agent support text-based refinement.
- Ten participants produced 46 videos over one week.
- The work received a UIST 2026 Best Paper Honorable Mention; the tool was not released as a commercial product.
What is changing?
Adobe Research detailed Project Doki, an experimental text-native generative-video interface, on November 5. Users define characters, settings, and visual style in one document, write scenes, add audio, and compile the text into video shots. Inline previews and a conversational AI agent help refine shots from the same document. The work received a Best Paper Honorable Mention at UIST 2026.
A week-long diary study involved 10 participants with varied experience who produced 46 videos. Participants reported a faster path from idea to draft and a clearer view of narrative structure, while model predictability, precise control, and temporal expressivity remained limitations. Project Doki is a research prototype; Adobe did not announce it as a generally available commercial product.
Explore the original sources
Source date: 5 November 2026.
Published by AI Radar: 6 Nov 2026, 13:02 (Istanbul, UTC+3).
FOLLOW THE TOPIC
Topics and tags
Share your discovery.
Send this story to a friend.
Reader comments
What do you think about this development? Share your experience or question. Comments are published after editorial approval.
Your name/nickname and comment become public if approved. Read: Privacy notice.



Loading comments…