272 H200 runs show what FLOP estimates miss in fine-tuning duration
Dharma-AI reports that a FLOP-only estimate produced a mean absolute error of 12.41 hours across 272 production SFT runs, while a CatBoost model trained on pre-dispatch information reduced it to 1.71 hours.
AT A GLANCE
Key points
- The study covers 272 production SFT jobs and about 7,382 H200 GPU-hours.
- Mean absolute error was 12.41 hours for the FLOP baseline and 1.71 hours for CatBoost.
- The predictor uses only configuration and model information known before dispatch.
- Results are specific to H200 SFT data, and errors increase in the sparse tail above 60 hours.
What is changing?
In a research preview published on November 18, 2026, Dharma-AI argues that estimating end-to-end fine-tuning duration from compute alone misses production overheads. The study covers 272 supervised fine-tuning jobs on a shared NVIDIA H200 pool, totaling about 7,382 GPU-hours. Duration was measured from the moment a job received its GPUs until completion; queue time was excluded.
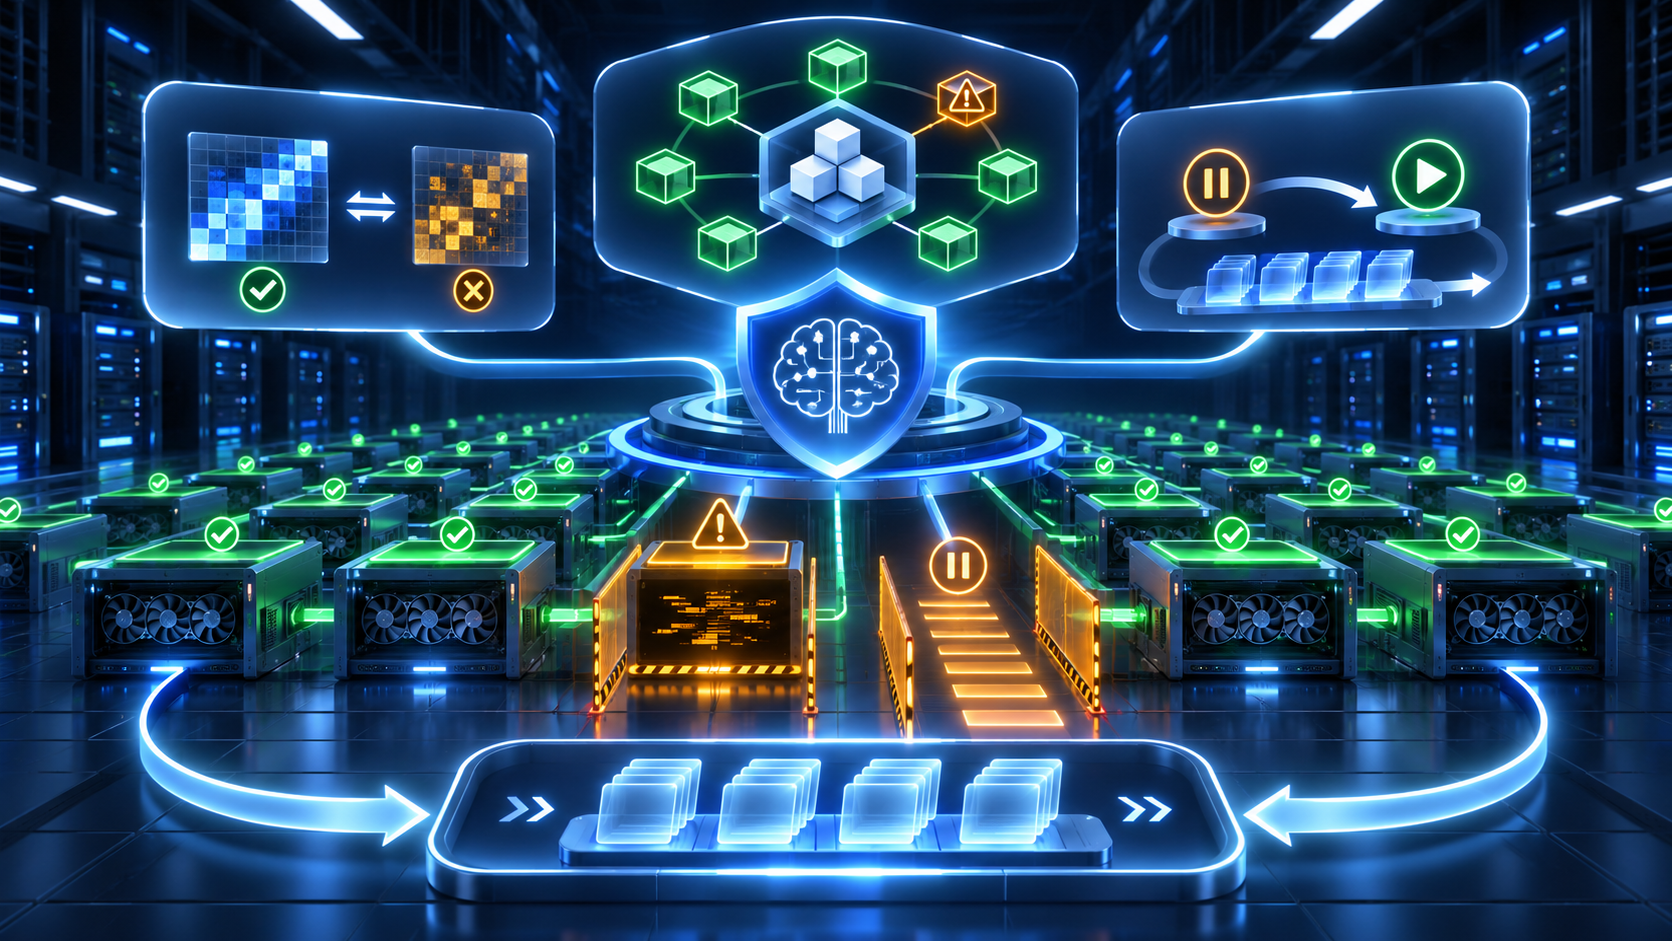
The common FLOP approach divides roughly 6·P·D operations for a dense Transformer by GPU count, peak performance and an assumed model FLOP utilization. It leaves out environment setup, model download and loading, tokenization, periodic evaluation, checkpoint uploads and final model transfer to object storage. Network and storage contention on a shared cluster can also make jobs with the same nominal compute finish hours apart.
In stratified five-fold cross-validation, the FLOP baseline at 30% MFU achieved R² of 0.31 and a mean absolute error of 12.41 hours. A CatBoost model using 24 configuration and model features known before dispatch reached R² of 0.98, mean absolute error of 1.71 hours and median absolute error of 0.51 hours. Eighty percent of predictions were within 2.20 hours and 90% within 4.31 hours. Leading features included total evaluation samples, trainable parameters, evaluation batch proportion, total parameters and checkpoint volume. These are associations, not causal findings.
The data includes only SFT jobs on H200 GPUs and models up to 15 billion parameters, covering both LoRA and full fine-tuning and the Transformers and Unsloth stacks. Median error rose to 5.19 hours for the 13 runs longer than 60 hours. The numerical results therefore should not be transferred directly to other GPU generations, RLHF, DPO or RLVR training, or different storage and network environments. Dharma-AI says a full paper will follow on arXiv; the current results are a team-authored preview, not an independent replication.
This report is prepared with AI assistance and checked against sources. Automated checks do not constitute human editorial review. Editorial approach
Explore the original sources
Source date: 18 November 2026.
Published by AI Radar: 19 Nov 2026, 11:02 (Istanbul, UTC+3).
FOLLOW THE TOPIC
Topics and tags
Share your discovery.
Send this story to a friend.
Reader comments
What do you think about this development? Share your experience or question. Comments are published after editorial approval.
Your name/nickname and comment become public if approved. Read: Privacy notice.
Loading comments…