KiteFishAI releases the 155M-parameter NanoI1 model for local enterprise AI
KiteFishAI’s Apache-2.0-licensed NanoI1 model targets local structured extraction, classification and routing workflows with 155 million parameters and a 2,048-token context window.
AT A GLANCE
Key points
- NanoI1 is available in Base and Instruct variants under Apache 2.0.
- Its 155.3 million parameters and 2,048-token context target short, bounded enterprise tasks.
- The model card lists explicit limitations for open-ended knowledge, complex reasoning and high-impact decisions.
What is changing?
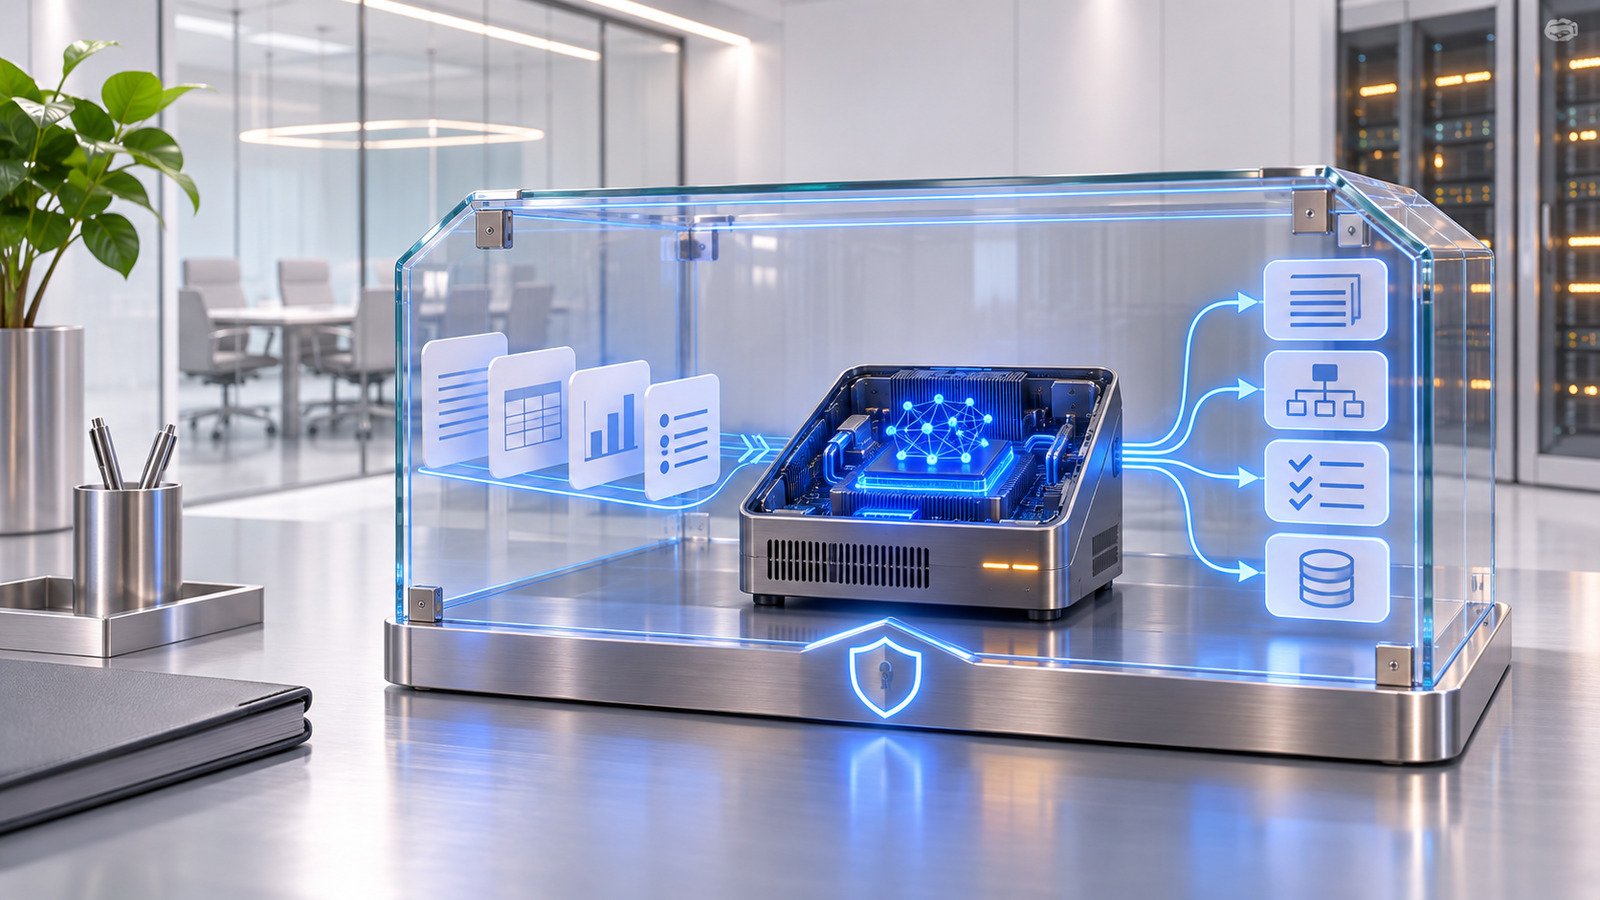
KiteFishAI has released NanoI1, a 155-million-parameter open-weight language model, in Base and Instruct variants. According to the model cards under the company’s verified Hugging Face organization, NanoI1 is designed for short-document extraction, classification, routing and brief grounded question answering when teams prefer not to send sensitive data to an external model. The weights are available under Apache 2.0. That license permits commercial use and customization, but it does not remove an adopter’s own data, security or regulatory obligations.
The model uses a decoder-only Transformer architecture with 155.3 million total parameters. KiteFishAI says it trained NanoI1 from scratch on roughly one trillion tokens, provides a 2,048-token context window and offers a separate Instruct variant for instruction following. That size and short context make it a more plausible starting point for bounded tasks such as KYC field extraction, support-ticket routing or classification of short forms than for processing long reports in a single pass.
The model card lists clear production limitations. NanoI1 is not recommended for open-ended factual questions without context, mathematics and multi-step reasoning, legal, medical or financial advice, or automated decisions about people. The company says the model can invent content and may add fields that do not appear in the source during structured extraction. Schema-constrained decoding, output validation and human review are therefore important for production extraction workflows.
KiteFishAI says the training mix includes multiple open datasets, each subject to its own license terms. The model card also states that preference or safety tuning has not yet been applied. Open weights and local deployment can reduce data movement, but task-specific fine-tuning, an evaluation set, access boundaries and output review remain the responsibility of the team deploying the system.
This report is prepared with AI assistance and checked against sources. Automated checks do not constitute human editorial review. Editorial approach
Explore the original sources
Source date: 18 November 2026.
Published by AI Radar: 18 Nov 2026, 09:59 (Istanbul, UTC+3).
FOLLOW THE TOPIC
Topics and tags
Share your discovery.
Send this story to a friend.
Reader comments
What do you think about this development? Share your experience or question. Comments are published after editorial approval.
Your name/nickname and comment become public if approved. Read: Privacy notice.
Loading comments…