
NVIDIA Nemotron 3.5 gives agents a multimodal document-retrieval pipeline
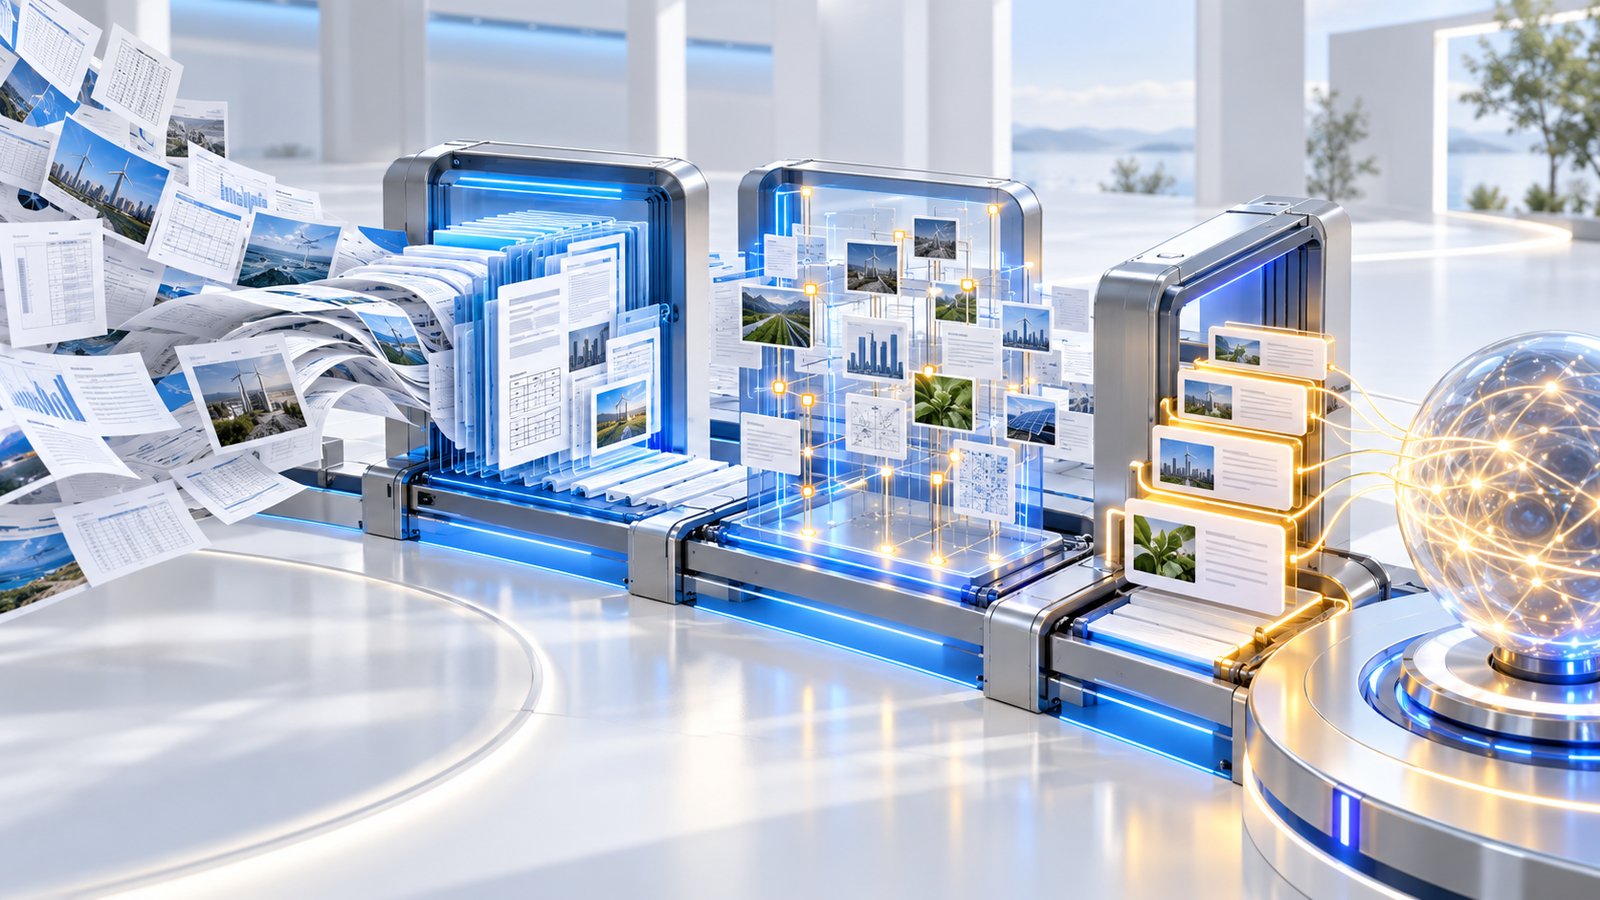
NVIDIA released open-weight Embed models for finding evidence across text and images, a Rerank model for reordering results, and a Parse model for structuring documents.
AT A GLANCE
Key points
- Embed models search text and visual document content together
- Rerank 8B reorders candidate evidence before it enters the agent’s context
- The 631M-parameter Parse model extracts tables and document structure into machine-readable output
What is changing?
NVIDIA expanded the Nemotron Retriever collection on October 21 with five new open models available for commercial use. The 8B and 1B Nemotron 3.5 Embed variants search text as well as tables, charts, schematics, and document images; the 1B model is available in BF16 and NVFP4 formats.
Nemotron 3.5 Rerank 8B jointly evaluates queries and candidate documents to reorder the evidence that enters an agent’s context. In NVIDIA’s fixed-agent experiment, adding the reranker to Embed 8B reduced total agent token cost by about 14% while improving retrieval accuracy. That figure comes from the provider’s stated setup.
Nemotron 3.5 Parse, with 631 million parameters, converts document images into Markdown, HTML tables, and structured blocks while preserving reading order, tables, charts, and location information. Weights and training recipes are on Hugging Face, and the models can also be deployed through NIM and several inference providers.
Explore the original sources
Source date: 21 October 2026.
Published by AI Radar: 22 Oct 2026, 01:06 (Istanbul, UTC+3).
FOLLOW THE TOPIC
Topics and tags
Share your discovery.
Send this story to a friend.
Reader comments
What do you think about this development? Share your experience or question. Comments are published after editorial approval.
Your name/nickname and comment become public if approved. Read: Privacy notice.





Loading comments…