AWS adds quality, speed and cost rankings to JumpStart
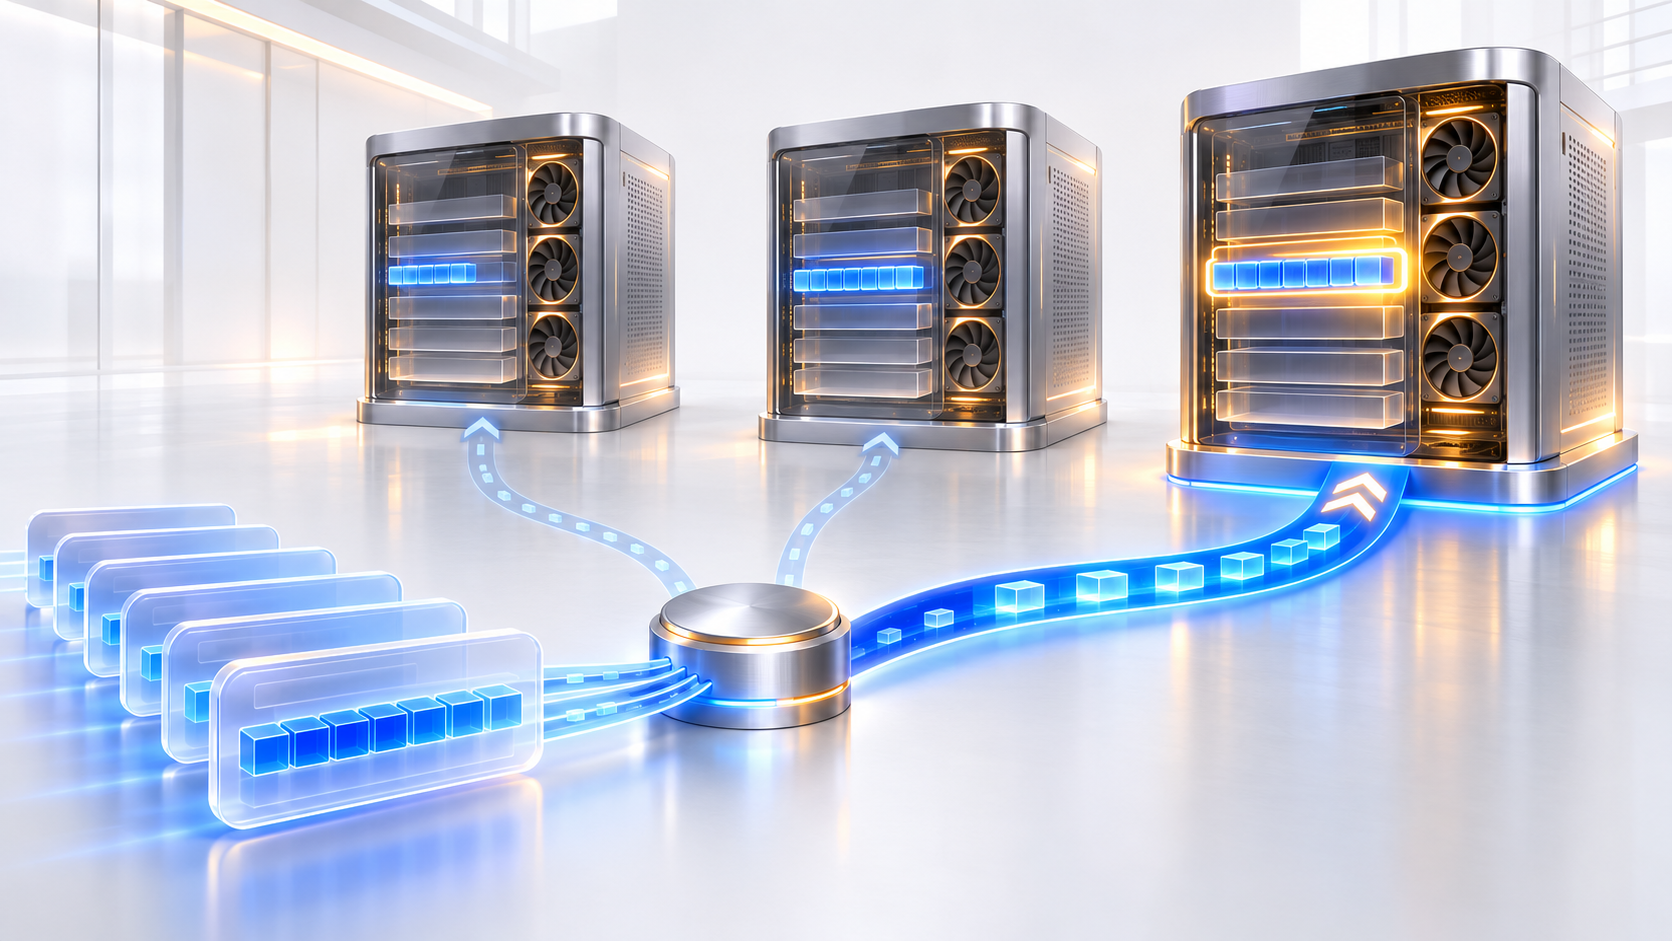
The Amazon SageMaker JumpStart Model Leaderboard now compares more than 70 open-weight models using consistently measured quality, speed and estimated infrastructure cost.
AT A GLANCE
Key points
- The launch covers more than 70 open-weight models
- Quality, first-token latency, throughput and estimated hourly cost appear together
- License, provider and modality filters work with use-case profiles and optimization goals
- AWS positions the leaderboard as a shortlist tool, not a substitute for testing on your own data
What is changing?
AWS added a Model Leaderboard view to the JumpStart catalog in Amazon SageMaker Studio on November 18, 2026. At launch, the view compares more than 70 open-weight foundation models from providers including Meta, Google, Qwen, IBM and Arcee. Rather than combining scores published by different teams under different settings, AWS presents models measured through a common evaluation and deployment method.
For quality, the leaderboard reports BIG-Bench Hard, GPQA Diamond and MMLU-Pro separately. Operational metrics include time to first token, tokens generated per second for each request, and the estimated hourly cost of the default instance. AWS says it runs quality benchmarks with one evaluation harness and measures speed and cost by sending a standard workload to real JumpStart deployment configurations.
Users can first narrow the catalog by hard requirements such as license, provider, and input or output modality. They can then select a use-case profile and choose Balanced, Cost optimized, Latency optimized or Throughput optimized. Balanced targets the lowest estimated cost per token, while the other goals prioritize hourly price, first-response latency or generation speed. Teams can also share the configured view through a direct URL.
AWS notes that the displayed cost reflects only the on-demand hourly price of the selected instance and excludes data transfer, storage, inference components and discounts. It also recommends treating close scores as ties and using the leaderboard to shortlist two or three candidates rather than make the final decision. Production selection still requires testing with the organization’s own data, prompts, latency limits and budget.
This report is prepared with AI assistance and checked against sources. Automated checks do not constitute human editorial review. Editorial approach
Explore the original sources
Source date: 19 November 2026.
Published by AI Radar: 19 Nov 2026, 03:04 (Istanbul, UTC+3). Updated: 19 Nov 2026, 04:11.
FOLLOW THE TOPIC
Topics and tags
Share your discovery.
Send this story to a friend.
Reader comments
What do you think about this development? Share your experience or question. Comments are published after editorial approval.
Your name/nickname and comment become public if approved. Read: Privacy notice.
Loading comments…