AWS adds live KV cache-aware request routing to SageMaker AI
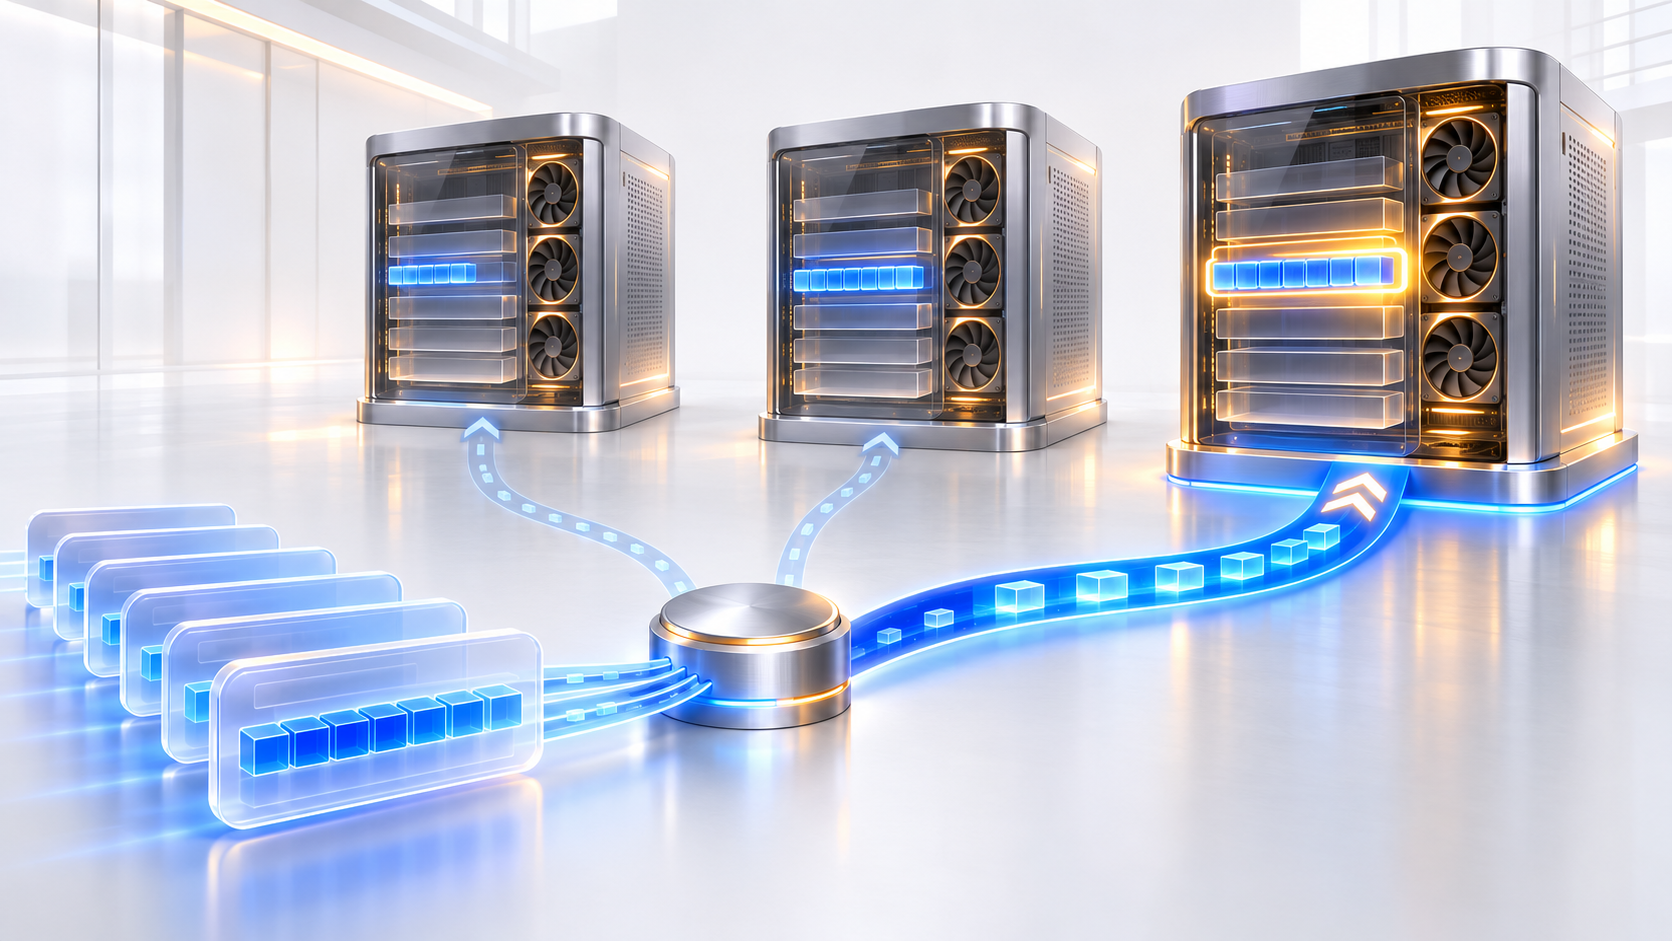
KV cache-aware routing uses live cache state to send long or repeated prompts to the GPU instance holding the longest match, falling back to load-aware routing when no match is available.
AT A GLANCE
Key points
- SageMaker routes requests to the GPU instance holding the longest matching KV-cache prefix.
- Load-aware routing takes over when no usable match is found.
- The feature requires at least two copies, vLLM DLC 0.33.0 or later and GPU instances.
What is changing?
AWS announced KV cache-aware routing for Amazon SageMaker AI real-time inference endpoints on November 16. A vLLM container reports the key-value cache blocks it stores and evicts. SageMaker compares the beginning of an incoming prompt with blocks across running instances and selects the instance holding the longest match, reducing recomputation of repeated system prompts, documents or conversation history.
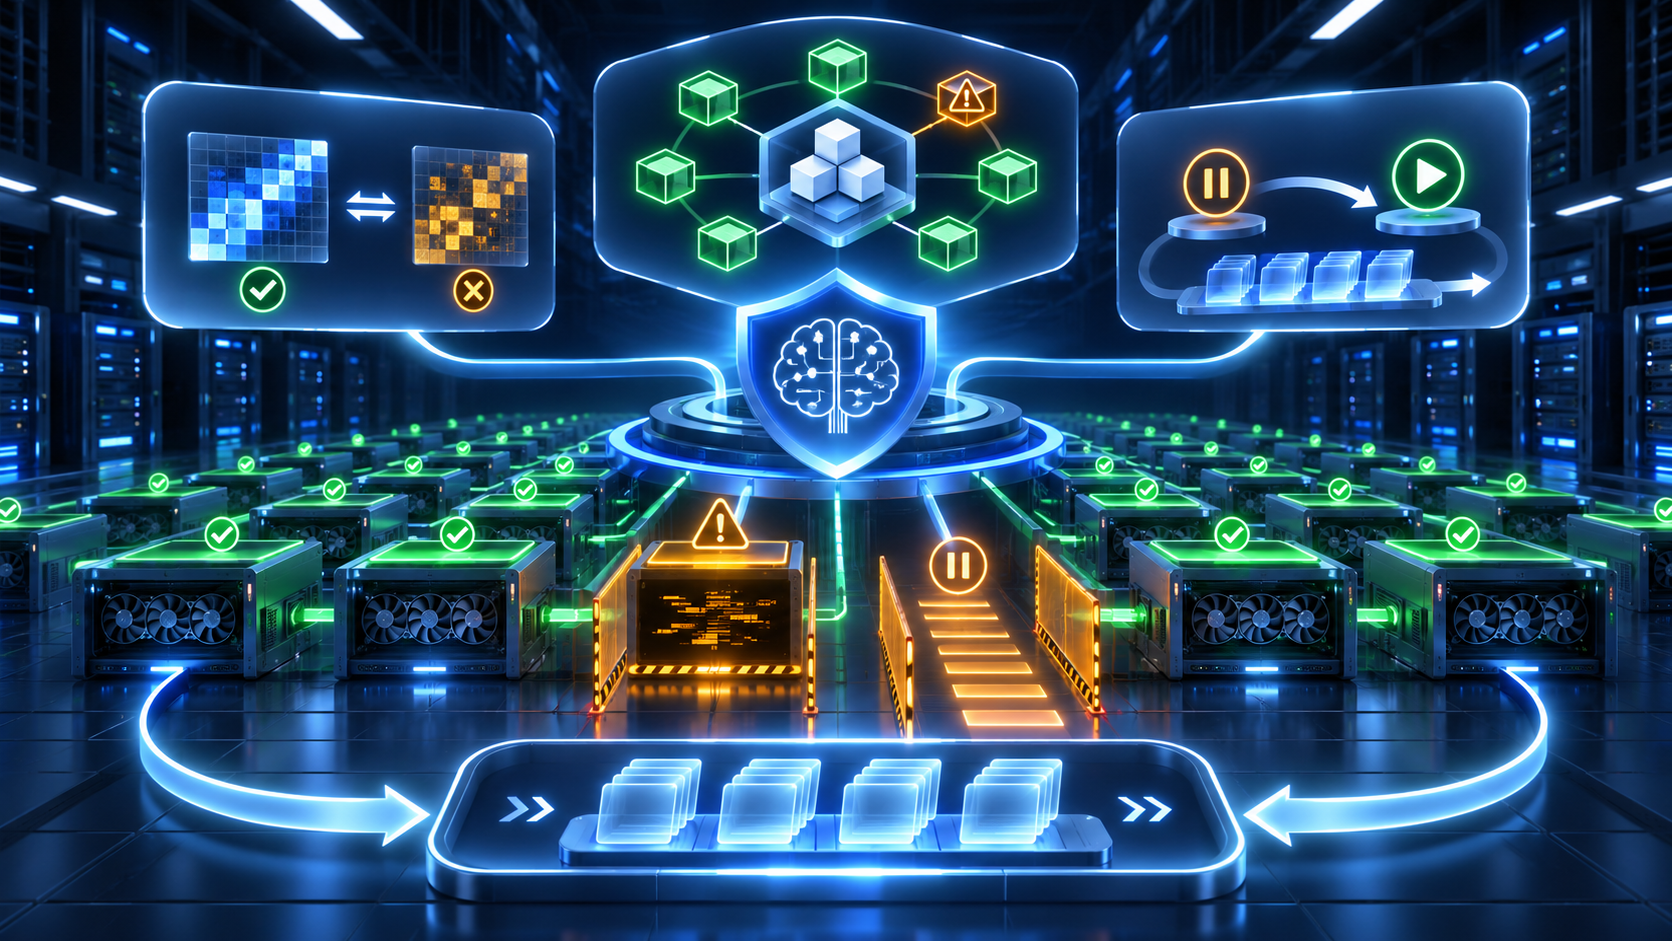
If the lookup is slow or no suitable match is found, the endpoint falls back to load-aware routing. AWS recommends prefix-aware routing for stable shared prompts, short prompts or moderate load, and KV-aware routing for long prompts, high load and constrained GPU memory. KV-aware routing is therefore not a universally better default.
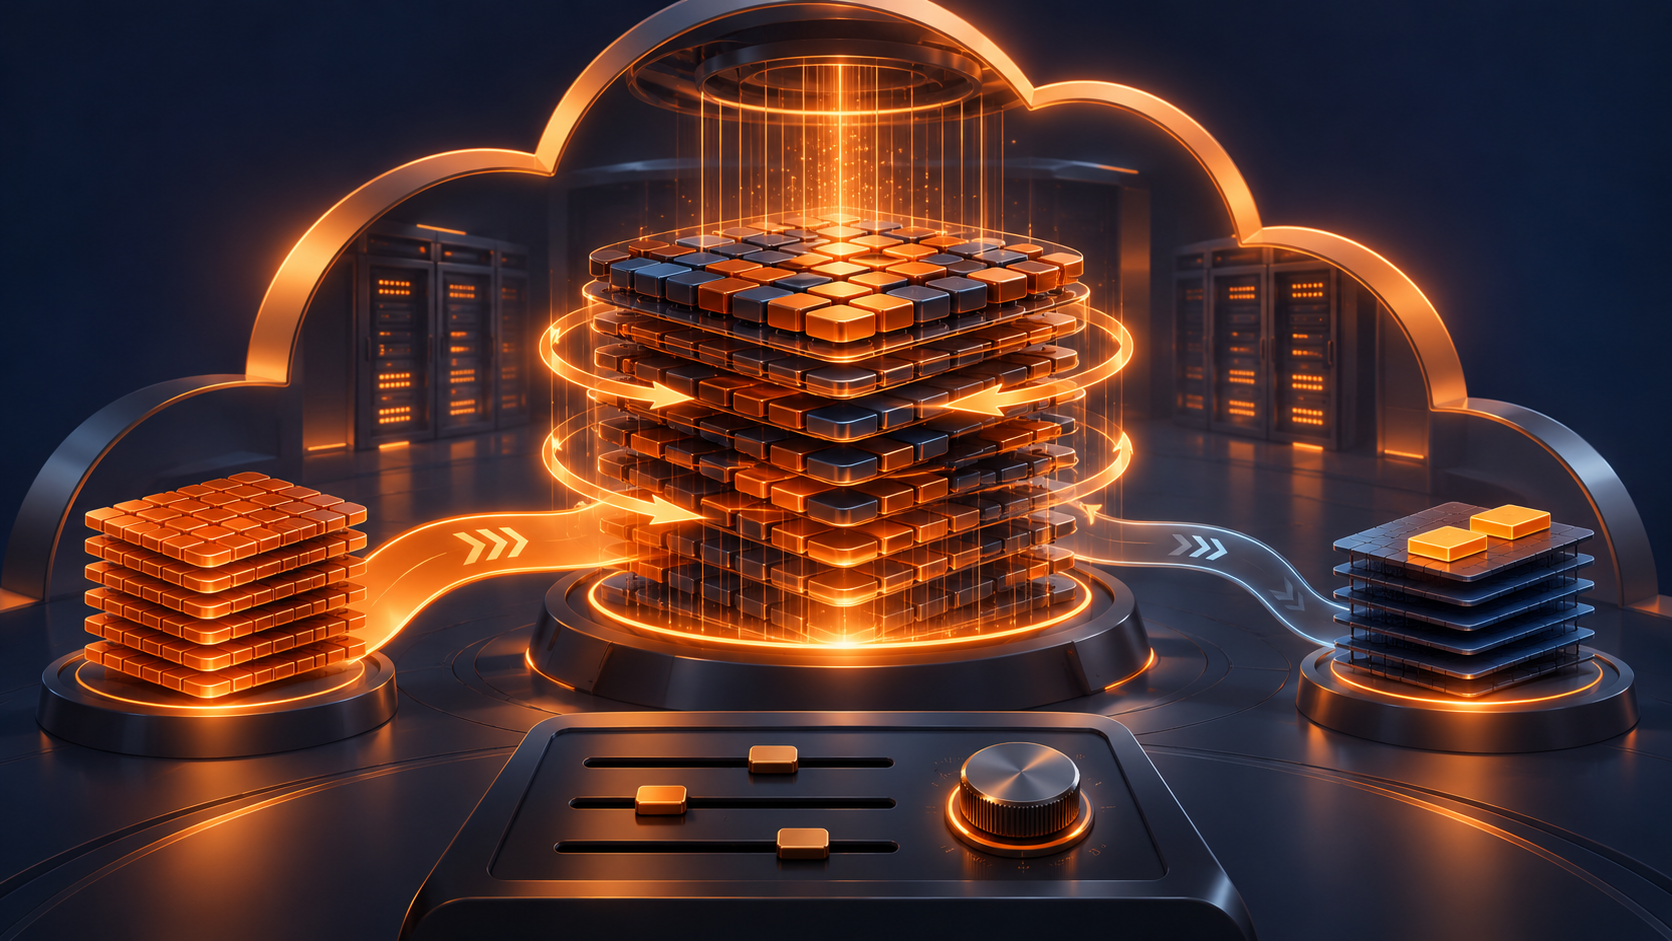
Teams enable the feature by setting RoutingStrategy to KV_AWARE on a production variant and adding an environment variable that reports cache events. Existing invocation APIs and OpenAI-compatible payloads are preserved. Single-model endpoints and inference components, including LoRA adapters, are supported. The setup requires at least two instances or copies, AWS vLLM Deep Learning Container 0.33.0 or later, GPU instances and a vLLM-based container.
AWS provides metrics including KV cache hit rate, charges no additional fee for the routing feature and offers it in every AWS Region where SageMaker AI is available. A separate HyperPod document’s /completions requirement applies to that deployment path and should not automatically be generalized to the real-time endpoint announcement.
This report is prepared with AI assistance and checked against sources. Automated checks do not constitute human editorial review. Editorial approach
Explore the original sources
Source date: 16 November 2026.
Published by AI Radar: 18 Nov 2026, 01:05 (Istanbul, UTC+3).
FOLLOW THE TOPIC
Topics and tags
Share your discovery.
Send this story to a friend.
Reader comments
What do you think about this development? Share your experience or question. Comments are published after editorial approval.
Your name/nickname and comment become public if approved. Read: Privacy notice.
Loading comments…