Hugging Face begins routing language-model requests through OpenRouter
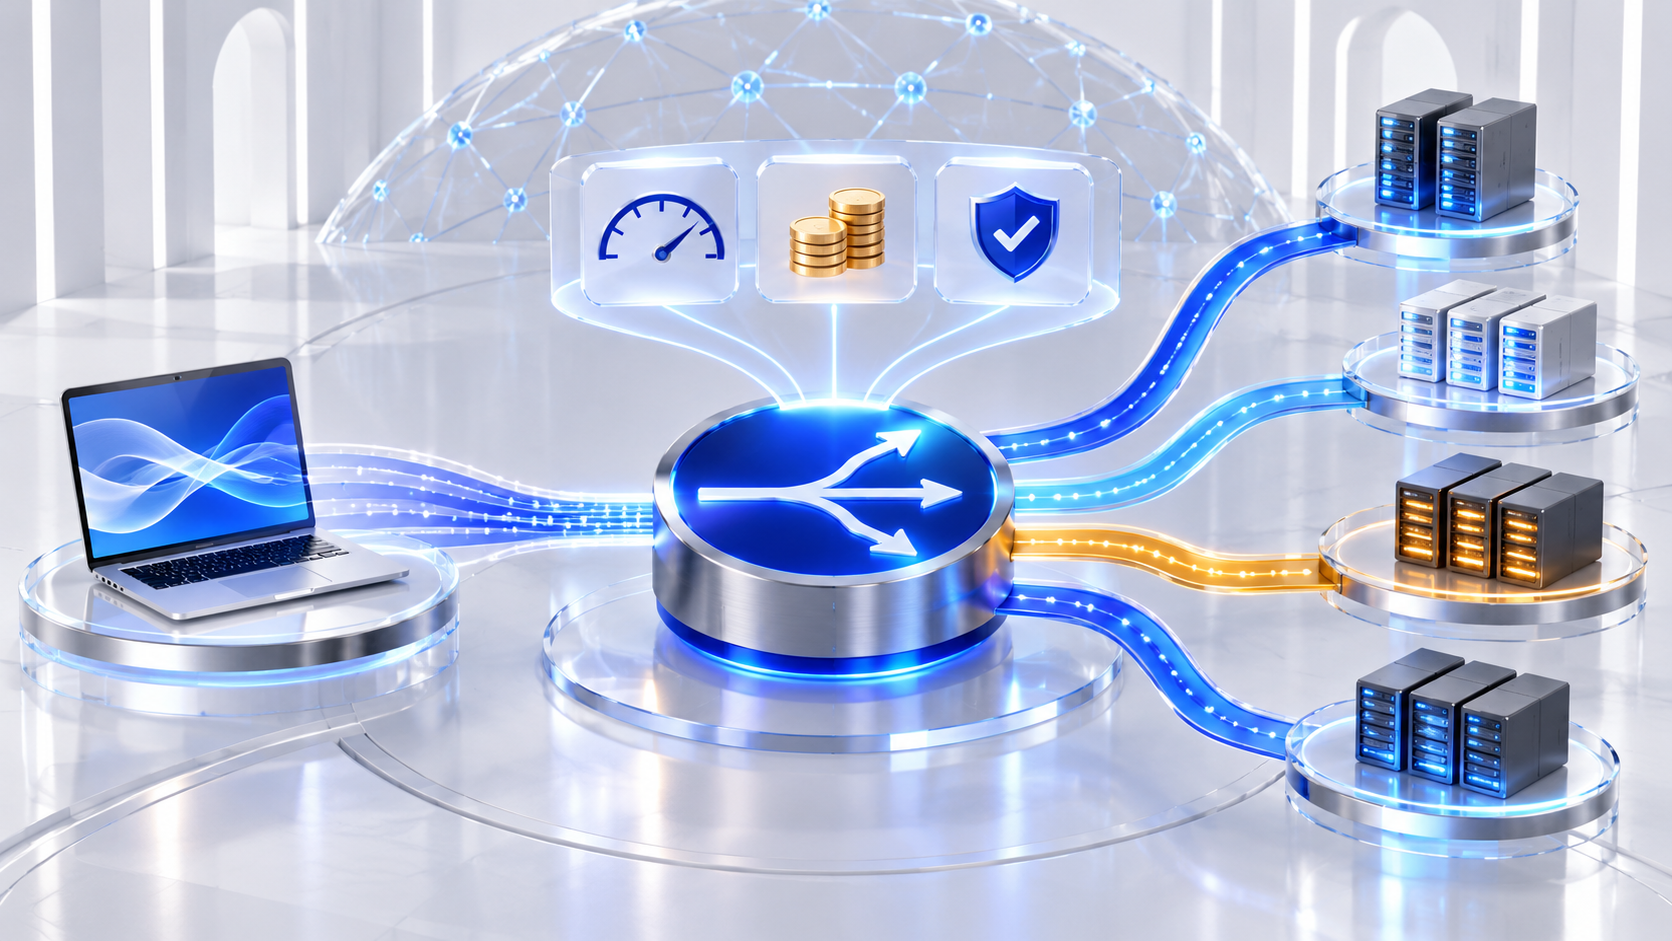
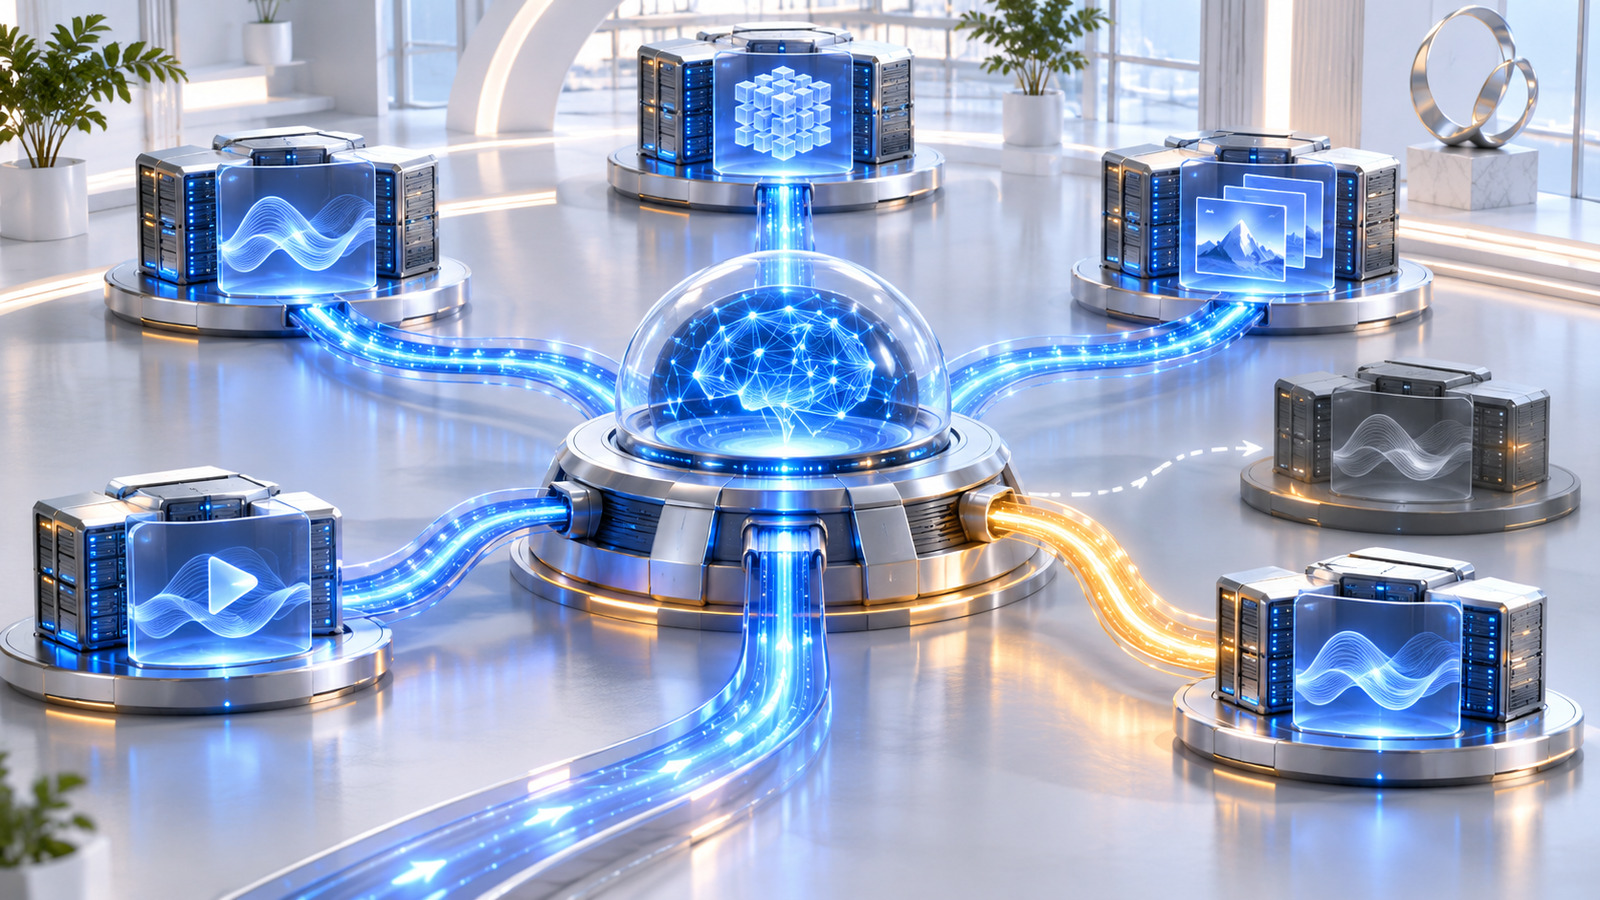
Hugging Face Inference Providers now uses OpenRouter for language-model requests, selecting providers by live price, speed, and reliability without requiring application-code changes.
AT A GLANCE
Key points
- Language-model requests now use OpenRouter’s router
- Provider selection uses live price, speed, and reliability signals
- Image, video, and audio generation flows are unchanged
What is changing?
Hugging Face announced that language-model requests in Inference Providers now use OpenRouter instead of its custom router. The new layer selects an available provider based on live price, speed, and reliability signals, while Hugging Face says existing code continues to work. Access uses a Hugging Face token with the “Make calls to Inference Providers” permission, and usage is billed to the user’s Hugging Face account or organization.
The change applies only to language models; image, video, and audio generation continues to run directly through Hugging Face Inference Providers as before. Users can no longer bring their own provider API key for language models. Hugging Face also says PRO users receive $2 in monthly credits, while Team and Enterprise organizations receive $2 per seat. Smart routing may improve resilience, but teams should test data-region, latency, and cost policies before production deployment.
This report is prepared with AI assistance and checked against sources. Automated checks do not constitute human editorial review. Editorial approach
Explore the original sources
Source date: 16 November 2026.
Published by AI Radar: 16 Nov 2026, 21:08 (Istanbul, UTC+3).
FOLLOW THE TOPIC
Topics and tags
Share your discovery.
Send this story to a friend.
Reader comments
What do you think about this development? Share your experience or question. Comments are published after editorial approval.
Your name/nickname and comment become public if approved. Read: Privacy notice.
Loading comments…